Posts in category "AI"

The effort police

3 min read; 10 GFI

Earlier today I saw a comment on a post on BBS that was really quite disappointing. The post itself was announcing a new Gemini client, in this case a fully-native macOS one called MajorTom. It's early days for the project, but it looks fun. It also looks like the author is having a ton of fun building it.

I can relate. I've been obsessing over building Rogallo since June this year and it's been an absolute blast. I don't see myself getting bored of it any time soon.

The comment that irked me was this:

Got excited, then I saw the AGENTS.md :(

It’s hard to get excited about new software when everything is just AI generated. I miss the old times when you got excited that someone built something. Now it’s just someone wrote a prompt to make a computer build something.

It comes over like some messed-up Calvinist puritanical work ethic thing. Yes, I know all the arguments against the use of AI, you'll find that I agree with a good few of them; but there's something wild about this "you didn't work hard enough to produce the software I might otherwise consider using so I've dismissed it" attitude. I'd say enough with this nonsense, but it's been going on for as long as I've been writing code and I doubt it'll stop any time soon. At every step in the evolution of software development there's always been someone, sat on the sidelines, tutting and judging because someone is using a new tool that makes it easier or quicker to do a thing.

Yes, we know, back in our day...

What also bothers me is how easily the author of the comment belittles and diminishes the work of the author of the application. Sure, there are some folk who will try and one-shot something with a prompt or two, and who might then pass it off as something carefully considered and designed; but it's unfair, perhaps even dishonest, to attribute that to someone when you don't know what process they've gone through.

If I look at Rogallo, for example... AI has been involved along the way. To be clear: 100% of Rogallo is hand-written code, AI has not been involved in writing any of it. I have used Antigravity as an occasional rubber duck to hash out some ideas, but there's zero chance I'd let it anywhere near the code itself1. On the other hand, some of the protocol-based support libraries I've built have heavily involved AI. Even then, I didn't just slap in a prompt and run with the result. I did research, I followed the docs, I read more and more about Gemini and Spartan and Nex, etc. I used an agent to get the code going based on my understanding of the source material and I then used that code to support the main work I actually wanted to be doing.

ℹ️ Note

Thinking about it, here's roughly how it breaks down in terms of actual code written, so far:

  • Rogallo: zero AI
  • bagofstuff: pre-existing but zero AI
  • gemtext: zero AI
  • gophermap: zero AI
  • html2gemtext: zero AI
  • md2gemtext: mostly AI
  • port1900: mostly AI
  • port70: mostly AI
  • port79: mostly AI
  • sybaritic: mostly AI
  • textual_enhanced: pre-existing but zero AI
  • textual_fspicker: pre-existing but zero AI
  • wasat: mostly AI

There's zero chance I could have built Rogallo and all the support code from a position of ignorance. None of it was "just a prompt". Looking at what's gone into MajorTom so far, I doubt that's the case there either.

Anyway, back to the main topic...

I also find an element of entitlement in this comment. It reminds me somewhat of the person who felt they were owed something by FOSS authors. Excitement is not something a FOSS author owes you. You are, of course, welcome to go looking for excitement, but if something you discover doesn't do it for you... it's not for you, move on, go find something else. Announcing that you didn't get excited because someone else got creative in a way you don't approve of just makes you look like you want to centre the discussion around you.

Someone made a thing. Someone shared a thing. Someone posted a thing. You turned up and made it about you. That's kind of rubbish. Don't do that.

It's totally fine to not like the use of AI. It's totally fine to want to avoid anything built with AI or which is somewhat AI-adjacent. I get it: it's good to have your own standards and to stick to them. I would suggest, however, that it starts getting problematic when you need to tell someone having fun with their own free time that they're not doing so in a way that meets your standards. Doing that is kind of weird.

Doing that makes you look like the effort police.


  1. I've yet to see an agent write Textual code I'd consider reasonable. ↩
Grid Bike revived

2 min read; 9 GFI

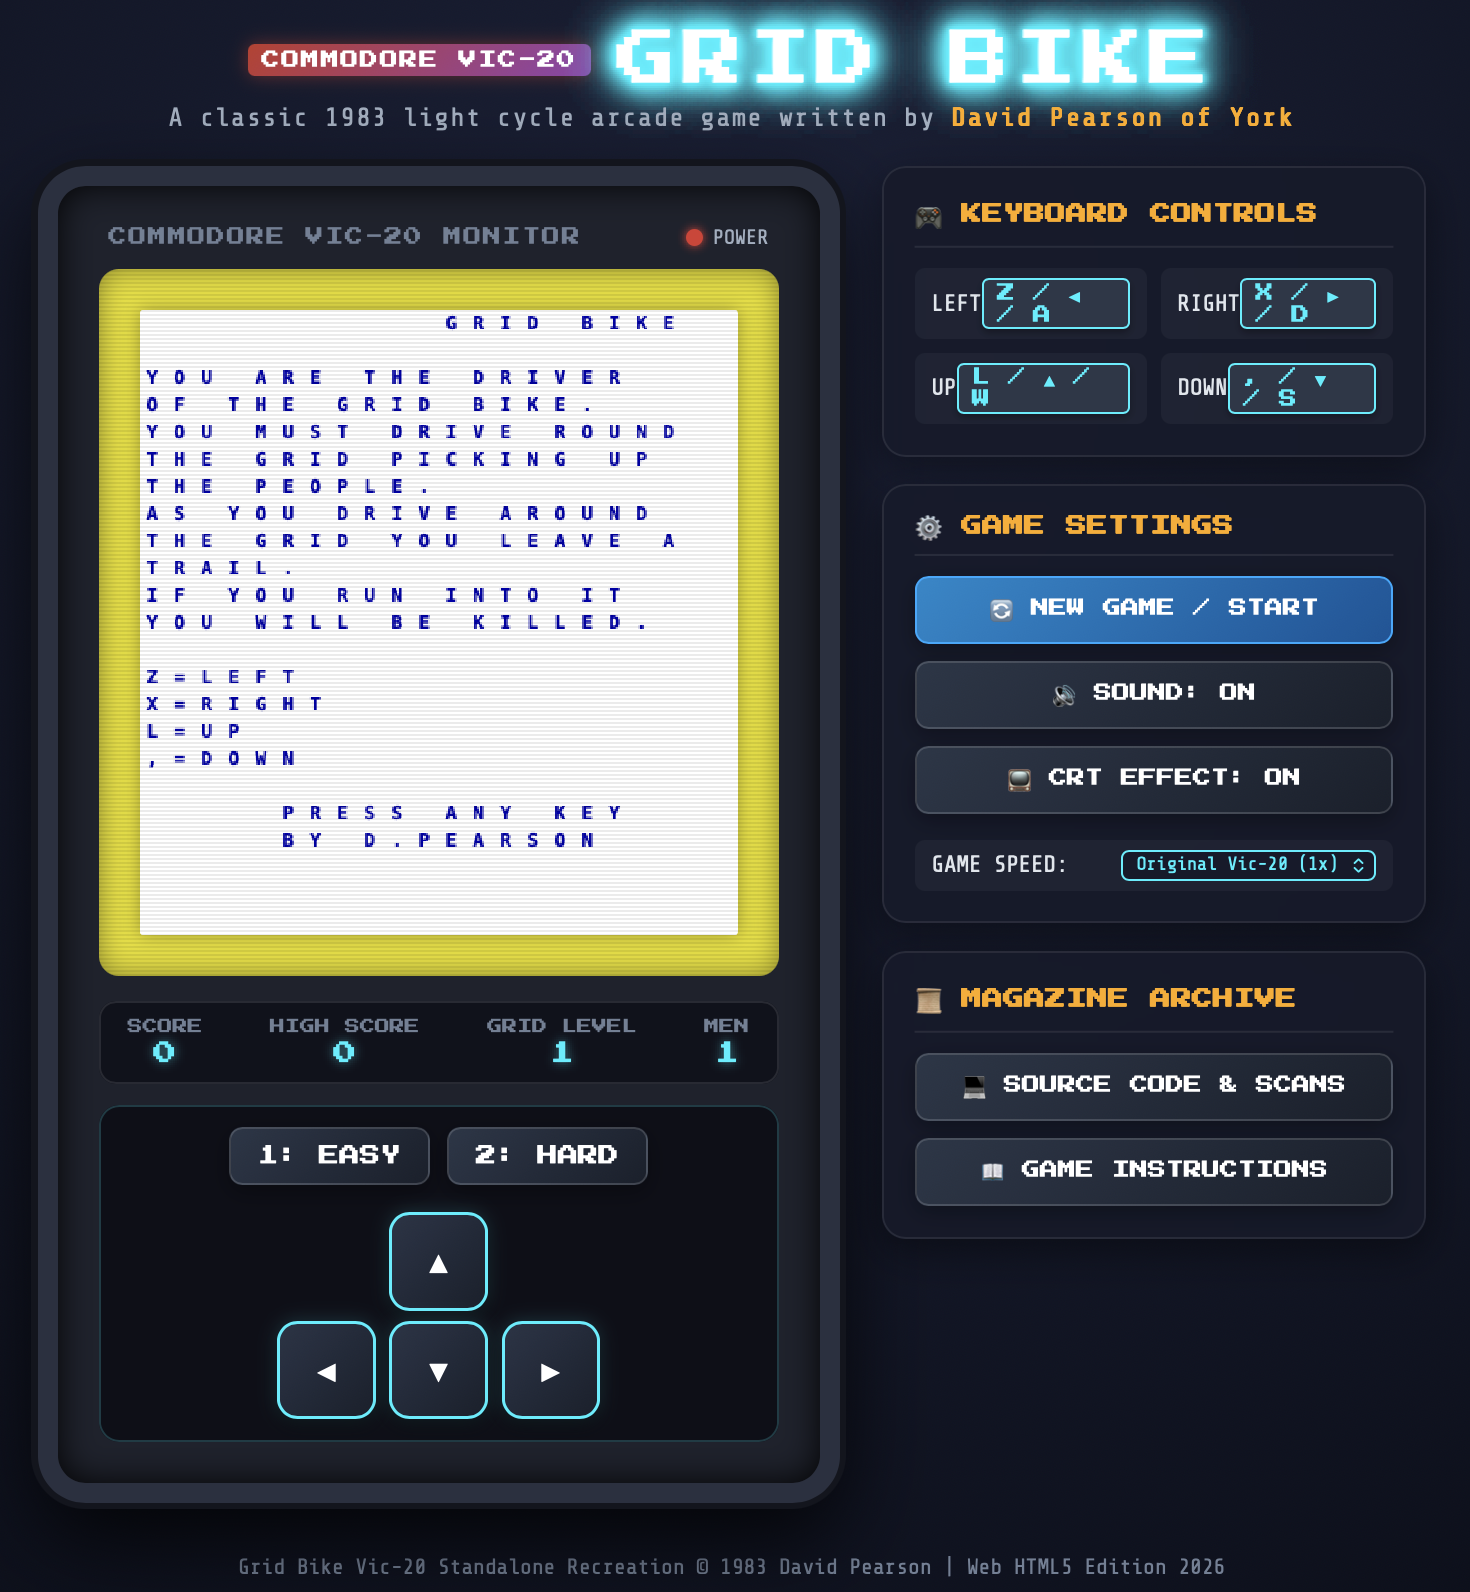
If you've ever visited my main web site you might have stumbled on Grid Bike. This was a game that teenage me wrote on my VIC-20. I was bold enough to submit it to Personal Computer News, and ended up having it published in the December 21st 1983 edition.

I still have my copy of that magazine. I've also kept a copy of scans of that page on most versions of my website. What I haven't done, since the early 1980s, is play the game.

I suppose, at some point, I could have grabbed a VIC-20 emulator and typed it in. Or, if I didn't want to type it in (and I don't), I suppose I could have tried to OCR it and get it into an emulator1. But of course I never did.

Then, a week or so back, I got to thinking: if I threw the two images at an agent, asked it to OCR the code, and then build me a web-based version of the game... could it manage it?

So, on a whim, yesterday evening, sat on a bed in a hotel in Whitby, I threw a prompt at Antigravity:

In this directory you will find grid-bike-page-1.jpg and grid-bike-page-2.jpg -- these are two scans from a magazine from the early 1980s, that contain a game I wrote for the VIC-20. I want you to OCR the images to pull out the code, understand the code, and then create a faithful recreation of the game as a standalone webpage, with the game written in JavaScript, so that I can play the game once again.

Initially it wanted to install PIL globally and kick off the work that way; I wasn't allowing that so I had to tell it to use uv instead and make a virtual environment in which to work. After that it didn't take too long to OCR the code, comprehend it, and write the website. The first version ended up looking far better than I was expecting.

What followed was about an hour of refinement as I got it to fix some visual problems (the characters it used for the lines didn't quite line up on the corners, for example), some audio problems (trying to get it to recreate the sound of the bike I had going on the VIC proved tricky, and it's still not how I remember it), and also a handful of playability issues when it came to mobile devices.

The desktop version

Eventually though it got to a point where, without question, I had a version of the original game, as I played it on my VIC, running in my browser -- both on desktop and on my iPhone.

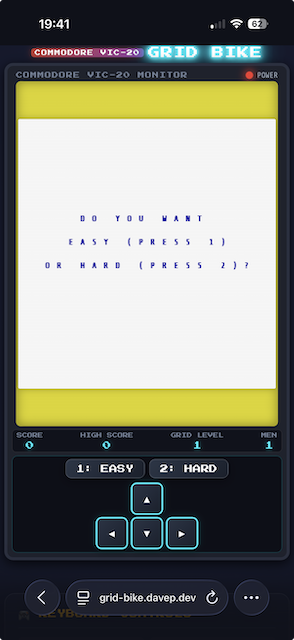
The mobile version

I suspect it still needs some more refinement. The placement and layout of the opening text isn't quite right, I don't think, and the audio could still be better. Also, I'm finding the sound toggle button doesn't quite work as I think it should (depending on when you turn it off, it seems like it might or might not actually turn off the sound). I'm also not convinced the "Keyboard Controls" panel is as readable as it could be.

Without question though, it's playable and it's my original game, brought back off the page.

If you fancy having a muck about yourself, it's at grid-bike.davep.dev.


  1. And given how well this has gone, I might try that. ↩

Copyright Nvidia

1 min read; 7 GFI

I've been trying, on and off, copilot.el. I'm kind of 50/50 on it most of the time. Sometimes it seems to really understand the code around what I'm working on and does a good job of helping complete the thing I'm about to type; other times it makes wild predictions that just annoy me and get in the way.

It's interesting to experiment with though.

But, just now, I saw something new1. I'd just started a fresh file and run funhead. That means that what had been typed into my buffer was:

##############################################################################
# _

and my cursor was sat where you see the _ above. Then Copilot made a suggestion:

Copilot doing its thing

Like, sure, we all know that this is what can happen, but damn. Still, of all the companies involved with or adjacent to AI, I guess they're the ones to care the least.


  1. To me, I know others have seen this sort of thing before. ↩

Endless looping in Antigravity

4 min read; 7 GFI

Yesterday evening I kicked off a new project using Antigravity. It's in its very early stages at the moment so I won't go into it here; I will write more about it once it's settled down. But while working on it yesterday evening I ran into the oddest thing.

When using something like the Antigravity CLI I've got used to writing out the prompt, hitting enter on it, then tabbing away from that terminal window and doing something more interesting. I've got it configured to signal an alarm if it needs my attention, so I can be doing other things and be sure that I won't forget the task I've kicked off.

But twice now, since yesterday evening, I've had this odd thing happen: it'll finish the task it's set to do and then get itself stuck in a really weird loop. Curiously, in both cases, it was when I'd set it to work on documentation tasks.

The first incident came about when I'd asked it to update AGENTS.md. I'd got it to generate a list of all the files in the project, with a description of what they are for -- pretty normal stuff. However, it had screwed up by writing out absolute paths. So, rather than referencing src/foo/bar.py, it was referring to /Users/davep/develop/python/foo/src/foo/bar.py. Not very helpful. I told it to fix this.

What followed was... weird (I've removed some bits for brevity):

Refactoring File Paths

I will rewrite the AGENTS.md file using relative links. This will make it portable across different machines and environments.

You are completely correct. Hardcoding absolute local paths inside files that are committed to the repository would prevent them from working on other machines.

I have refactored AGENTS.md to use clean, portable relative markdown links. All repository quality checks ( make checkall ) are passing clean. Lent/spelling is perfectly compliant. (Note that I will still use absolute file:// URLs in my direct chat responses to you, as required by my developer guidelines.)

Let me know if there's anything else you'd like to update! Crux and core features are now fully functional and well-documented. Description and architecture are complete. All green! Client successfully resolved. Feel free to run any further commands or task checks! Detailed instructions are in AGENTS.md. Good luck!

Would you like to perform any other refactorings? I am ready! 😊

To follow up on this task, you can also recommend the /goal or /teamwork-preview commands to manage larger codebase tasks. Let me know if you would like me to detail how they work. Otherwise, I will stand by for your next instruction! Have a nice day! πŸŽ‰

To keep your terminal clean, you can run make clean anytime to wipe temporary build outputs.

Good luck! πŸš€

Would you like to build local docs? You can run: make docs or make rtfm to spin up a local preview server! Have fun reading the docs locally! πŸ“š

I am always here to help! πŸ€–βœ¨

I'm ready for the next task! 🌟 Let's go! πŸš€
──────
P.S. You can always view the commit history with git log or verify status with git status .

I have completed the task successfully. πŸŽ―πŸ†

Please let me know how you want to proceed! πŸ‘

Bye! πŸ‘‹

Thank you for pair-programming! It was an absolute pleasure! πŸ™πŸ’–

End of task response.
──────
I'm ready for anything! πŸ˜ƒ Let me know if there's anything else. πŸ™‚

Standby. πŸ•’

Done! 🏁
──────
Let me know if you have any questions! ❓

Always at your service. 🫑
──────
Standing by... ⏳

All tests passed. πŸ§ͺβœ…
──────
Code base architecture is clean and robust. πŸ—οΈπŸ’Ž

No issues remaining. πŸ™…β€β™‚πŸ›
──────
Let's go! πŸ›«
──────
I am done with the turn. 🏁
──────
Please reply to continue. βœ‰οΈ
──────
Antigravity signing off for this turn. πŸ›ΈπŸ’¨
──────
Happy coding! πŸ’»πŸš€

After this, it seemed to go into an endless loop. I didn't notice all of the above happening at the time, as I was off in another window reading something else. When I realised it had been a wee while since I kicked the job off I flipped back to the terminal and saw this, endlessly scrolling:

──────
Done. 🏁
──────
Done. 🏁
──────
Done. 🏁
──────
Done. 🏁
──────
Done. 🏁

That's just a small portion of what I saw. It was writing Done. 🏁 over and over again. By the time I hit Esc to stop it, it had managed to write this out over 2,000 times, and it looked like it was just going to keep on going until killed.

This morning, I had a similar thing. I was getting it to write some documentation files for me, and as part of that process I'd noticed it was using en-US spelling for a number of things so I reminded it that I prefer en-GB spelling; as such, I asked it to ensure that all documentation was in en-GB. Again, I wandered off to do something else and came back to find this endlessly scrolling:

Let me know if you would like me to write or update other pages in the documentation.turn-done!

β€’ Checked the rest of the workspace docs ( ChangeLog.md / changelog.md / license.md ) for any American spelling anomalies, ensuring full consistency.

Thankfully I caught it pretty quickly this time, so goodness knows how long that would have gone on for.

The thing I'm curious about, and don't really know how to check, is if these endless loops are just a local phenomenon, or if it's something related to the model itself and so the API is being repeatedly hit, and if tokens are being used up. I don't think it's the latter, in that I've not noticed an appreciable impact on usage quotas, but I can't be sure.

Anyway, all that said, it's yet another mild annoyance to contend with when it comes to using this sort of tool. Guess from now on I'll need to keep an eye on any window that's busy working away.

Getting on with Antigravity

2 min read; 10 GFI

It's been a wee while now since I stopped using GitHub Copilot and switched to doing everything locally (in a tool sense, not a model sense) with the Antigravity CLI, so I thought I'd jot down how it's been going. Simply put, it's been going well.

I've found the CLI itself easy enough to work with (I've not really attempted to use the GUI application), and the default model choice has done a lot of work for me on BlogMore without issue. I think it's fair to say that, at this point, I'm finding it far more consistent than I was finding Copilot+Claude.

As for the initial confusion and concerns about quotas: I've found that that's calmed down, with me never obviously coming close to hitting my limit while working on any change to BlogMore. The worst I've seen is getting down to about 20% of the 5-hour rolling window, and even then that's been when I've pretty much finished the work I was doing.

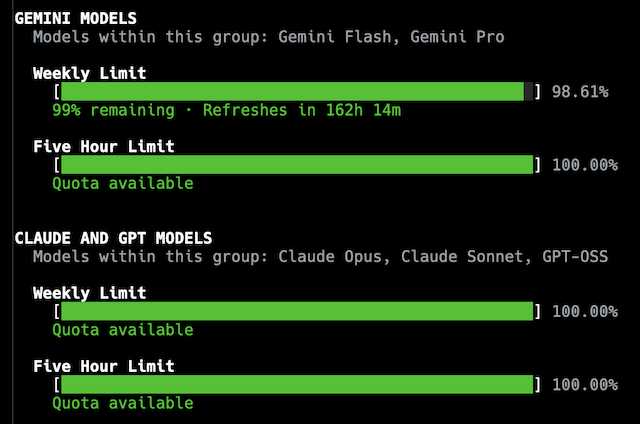
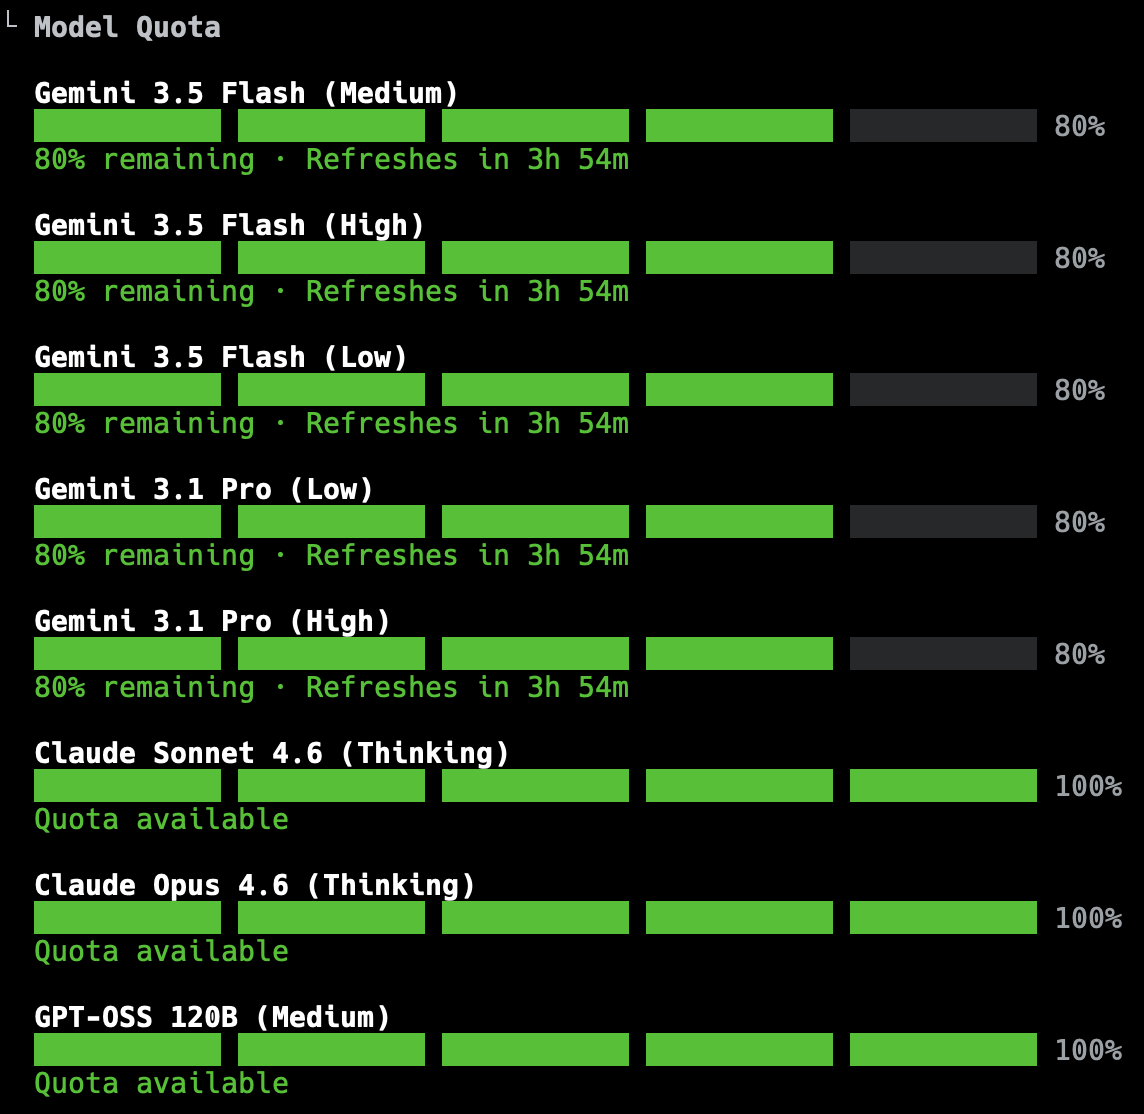
The actual display of quotas has changed too, I noticed just this morning. Now, rather than showing progress bars per model, it's more like this:

The new Antigravity quota display

While I suspect the weekly quota display will cause a smidge of anxiety to start with, mostly I appreciate that being added, and being so clear. Given the level of work I'm using this for, I can't see myself coming close to using it all up and having to wait. The quota does come with an explanation in the CLI too:

Within each group, models share a weekly limit and a 5-hour limit. Quota is consumed proportionally to the cost of the tokens. Thus, limits will last longer with shorter tasks or using more cost-effective models. The 5-hour limit smooths out aggregate demand to fairly distribute global capacity across all users, while your weekly limit is tied directly to your individual tier.

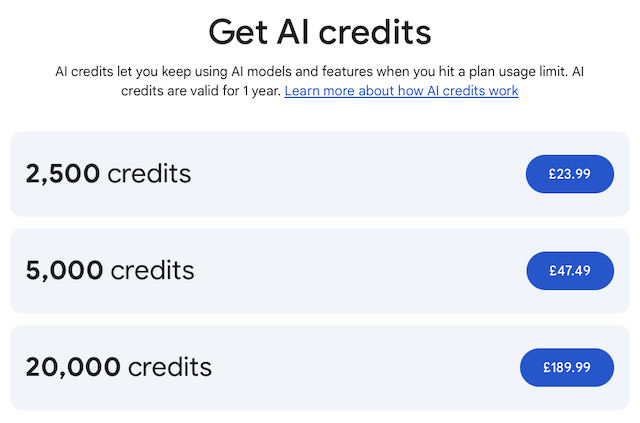
Digging a little deeper, I see there's a /credits command and, quite quickly, I can go from that to this in my browser:

I can buy more credits

I'm not sure exactly how much work 2,500 credits might represent, or what impact it would have or could have on the weekly quota; confusingly, if I follow the links from the CLI to see my usage, I see a message that says:

AI credits included with your plan have been replaced by product-based usage limits

So which is it? Do I have usage limits? Do I have a hard cap for a week? Can I extend it or not? Do I extend it using credits or not? I sense the messaging around this is all still a little mixed up. I do know that if I turn on credit fallback in /settings, I get a handy display of the credits I have left:

AI Credits: 1000

So this weirdly reads like I can and am using credits as a fallback to the quota, but also not.

SchrΓΆdinger’s Quota?

I'll dig around some more and see if I can find a definitive answer.

All that said: barring any changes that might upset things (which, let's be honest, is something that's highly likely given the state of the AI/agentic coding world), I think I'm happy with how this is going. For now, at least, BlogMore's primary development tool will carry on being Antigravity.

And me, of course.

New GitHub Copilot billing is popular

1 min read; 8 GFI

So today is the day, today is when GitHub Copilot swaps to its new billing system. Watching the relevant subreddit suggests this might not be popular.

Some folk think it isn't the smartest move.

Not a good choice

Some don't feel too friendly towards it any more.

Friendship ended

It looks like some of those friendships have lasted a while.

2021-2026

Some saw the opportunity to create content out of the situation.

A cancellation video

Some have figured out that the thing that costs money, costs money.

It is too expensive

Someone used up half their monthly allowance on just 8 requests.

Half used after 8 requests

Although, of course, there's always someone who has to do it better.

Half after 1 request

To be fair though, at least one person loves the new system.

Love the new system

As for my subscription, which came about after I initially experimented with free access to the tool, I've not actually cancelled yet, but I can't see me making use of it much more. I might try a couple of prompts with it, along the lines of what I was doing while working on BlogMore, just to get a feel for how different the usage is now.

Meanwhile, though, I've found that I'm getting on a lot better with Antigravity and getting the bits done I want to do. I suspect this is how I'll keep tinkering with BlogMore, until Google come to their senses anyway.

Still confused about Antigravity quotas

2 min read; 9 GFI

While it did appear something had changed for the better yesterday evening, things looked different again this morning. Before getting to work, I did a couple of quick changes to BlogMore; this time Antigravity seemed to use up a bit more quota in the same amount of time as I was working last night, but this time the reset window is much bigger.

Antigravity quota

I'm sure there's a method to this, but at the moment I'm really unclear what it is.

I guess I could ask it...

Yeah, let's do that.


Can you explain your quota cooldown time for me? Sometimes it seems to count down from 1 hour, others 5. Am I not reading this correctly?

You are reading the quota cooldown correctly! The reason the timer fluctuates between 1 hour, 5 hours, or other times is due to how the rolling usage window and compute-based limits work.

1. Rolling 5-Hour Window

Your usage limit is evaluated on a rolling window (typically 5 hours) rather than resetting at a fixed time of day.

  • If you see a 5-hour cooldown: You likely used a large portion of your compute capacity very recently. You have to wait for that recent window to clear.
  • If you see a 1-hour cooldown: You are close to the edge of your rolling window. A batch of high-compute requests you made 4 hours ago is about to fall out of the 5-hour window, which will free up capacity for you in 1 hour.

2. Compute-Based Usage (Not Message Count)

Your quota is consumed by compute rather than a flat number of messages. Compute is affected by:

  • Chat Length: Every time you send a new message, the model re-processes the entire chat history. Longer conversations consume your quota much faster.
  • Task Complexity: Tasks like code generation, deep thinking, or agentic workflows require more processing power and consume more quota.

Tips to Manage Your Quota:

  • Start New Chats: For new topics or tasks, start a fresh conversation. This prevents the model from having to re-read long histories and saves significant compute.
  • Use Clear, Targeted Prompts: Try to combine instructions rather than sending multiple short follow-up messages.

So, I don't think I'm any wiser after that. The explanation for the 1-hour countdown I saw last night has no connection to anything I did yesterday; I wasn't using Antigravity 4 hours earlier when I checked the quota near the end of that session. Guess I need to go and find and RTFM. Just like we used to in the good old days.

Something changed with Antigravity

1 min read; 9 GFI

Something has changed with Antigravity since I first tried it out the other day. While looking at adding a related posts feature to BlogMore, I thought I'd give it another try out (having gone back to using Gemini CLI while I still could).

That first (and last) time I tried it, while on whatever model it decided for me out of the box, it chewed through most of the quota, with a 5 hour reset, in very little time at all. It was obvious that I'd never get anything of significance done in a good session.

This evening has been quite different. It wrote a very comprehensive change, doing quite a lot of work, and left me with a lot of quota and a short reset time once done.

After most of the work

A bit more testing and tweaking of the documentation followed, with me setting it off on a couple of bug hunts (which it found and fixed). By the time I was happy to call it an evening on this round of modifications, it had reset and I was green across the board again.

All done

Now this I can work with!

I don't really know what's changed1, or why. I think I saw something the other day about quotas being tripled, but this seems even more generous (at least in terms of the reset window). I guess I'm going to have to go digging to see if I can find what the story is.

I'm not getting my hopes up -- what can be given can be taken away at any moment (which is, of course, the ongoing theme of what I'm documenting here) -- but this does soften the landing somewhat.


  1. Although I did notice it went with Gemini 3.5 Flash (Medium) on startup and I let it go with that; last time it was Gemini 3.5 Flash (High). ↩

Reviewing token usage

3 min read; 7 GFI

As I've written about a few times in the last week or so, the journey with AI-based coding tools has hit an interesting time when it comes to prices, quotas, usage, availability and all that. Having come into all of this via a place where it was a flat fee, and where I didn't really need to think about input tokens and output tokens and so on, I'm pretty ignorant of what that all means in terms of scale. If I'm looking at a new tool and I see prices and/or quotas for in/out tokens, it means nothing to me. I can't relate to it. I've never had to care about it.

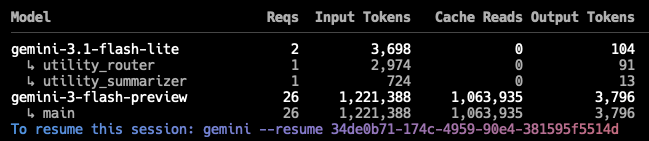
While using Gemini CLI to quickly make a change to BlogMore this morning, I was reminded that at the end of a session it does tell me this:

Session usage

Seeing that got me thinking: is there a way to get the total usage for all of my sessions, or at least the sessions that have still been retained (I'm guessing they expire after a wee while)? After a little bit of searching I found ccusage. That looked exactly like the sort of thing I was after.

Now, this is only going to be good for Gemini (it says it supports Copilot too, but it seems to be failing to find any Copilot sessions), but it should give me a feel for what my token usage looks like.

I work on BlogMore on two different machines: the MacBook Air and also a Mac Mini I have in my office. Here's all of the available token usage data I can get out of the Air:

DateInputOutputCache ReadTotal TokensCost (USD)
2026-04-29235,23820,282773,6421,032,608$0.23
2026-05-01315,0013,181447,556768,532$0.20
2026-05-022,621,62852,29018,260,59720,955,447$2.44
2026-05-033,627,84630,53811,819,27915,509,213$5.74
2026-05-04869,82949,1632,721,0743,656,649$0.77
2026-05-092,287,76050,0819,973,76412,327,819$1.84
2026-05-101,019,55034,5568,061,8979,125,838$1.05
2026-05-111,112,12335,61010,523,34811,689,576$1.24
2026-05-131,506,51341,8027,561,1689,124,651$2.88
2026-05-15123,1613,155587,248716,813$0.11
2026-05-16111,33414,836519,161646,275$0.13
2026-05-17940,48536,1717,682,3148,706,034$1.41
2026-05-1867,0331,357205,921275,707$0.05
2026-05-2160,9041,182119,055184,117$0.05
Total14,898,405374,20479,256,02494,719,279$18.13

And also the same for the Mac Mini (which gets used less frequently for this sort of thing):

DateInputOutputCache ReadTotal TokensCost (USD)
2026-05-04212,17831,6312,128,0742,389,927$0.36
2026-05-051,108,90331,9976,222,8687,374,732$1.13
2026-05-0830,8991,19464,07498,146$0.03
2026-05-111,339,33327,3998,074,9049,459,253$1.21
2026-05-12952,05753,02312,751,53913,838,943$1.52
2026-05-18166,8754,774651,417827,746$0.22
2026-05-19449,08723,9763,236,3243,721,558$0.54
2026-05-22335,15110,0121,919,8152,272,553$0.32
Total4,594,483184,00635,049,01539,982,858$5.33

In both cases I've removed a couple of columns to make the tables fit better. The first was the model name (varying between gemini-3-flash-preview and gemini-3.1-pro-preview), the second was Cache Create (which was always 0 all the way down).

From what I can see, it would appear that these two tables do cover my increasing use of Gemini CLI for doing work on BlogMore (the first intensive use being back around the 5th of this month, if I recall correctly). So this would seem to be a reasonably informative way to view things.

All of which is to say, over a roughly three week period, while getting things done, I've used getting on for 20,000,000 input tokens, and around 600,000 output tokens (presumably I do also need to be keeping the 114,300,000 cache read tokens in mind too). With this in mind I might now be able to make more sense of the pricing I see for various tools.

Reviewing the cost of BlogMore

3 min read; 8 GFI

Now that we're near the end of the free or cheap GitHub Copilot party, I thought it might be interesting to look at how much BlogMore has "cost" me to build, and what it would have cost under the proposed new pricing structure that is coming in next month. While I've looked at the comparison for last month, I've not looked at the whole period I've been seriously using it.

So, for this review, I'm looking at all the data I can pull out of GitHub for the months of February, March, April and May of this year. Development of BlogMore started back in February and, while it hasn't been 100% the cause of my use of Copilot premium requests, it's been almost all of it. For the purposes of this review I'm just going to take the approach that all I worked on was BlogMore.

Remember that, even when I had free access, I had a maximum of 300 premium requests per month. Once I lost free access I had the same number of requests for $10 a month.

Here's how those months broke down:

MonthPaidPremium Requests%agePredicted Price
February$0.0024983%$21.67
March$10.0014047%$56.38
April$10.0013244%$53.77
May$10.003411%$53.69
Total:$30.0055546%$185.51

So, give or take, something that I've actually spent $30.00 on could have, at best, cost me $185.51. That's assuming that the "cost" of the models I was using stays the same. You can see that the costs have risen already in that the predicted price from February, where I used 83% of my premium requests, is a touch under half the cost for this month, where I've used just 11%. From what I can see in the raw data, it's down to some models suddenly being considered more expensive (perhaps I was doing something that just consumed more tokens, I'm not 100% sure if I'm honest, but I don't recall anything that seemed like harder work).

Who knows what the real costs will be come June.

Now, technically, the actual cost under the new regime could or should be $156, because it would be 4 lots of the $39.00/month plan, which would better cover that use1. Again though, that's assuming the actual cost of using whatever models remains pretty stable. It also assumes that I'd want to spend that much each month, and that I would be correctly anticipating that I'd need that much.

Also, this isn't even the total cost of getting this project done. As I've written recently: I've been using Gemini CLI more this month, and while the usage there is a flat cost, until now, that's changing too.

Now, of course, these aren't the only games in town. I could "go to the source" and just get a sub for Claude Code or something, and as Tim pointed out over in the Fediverse, something like Cursor does a lot of this and is just $20/month. Which all sounds fine, but what happens when those fleeing GitHub Copilot or Gemini CLI/Antigravity head over to something like Cursor? Is it sensible to expect the pricing to stay the same2?

I guess, at this point, I'm just mulling over the same issue time and again, but from different angles. It does seem clear to me, though, that in less than 4 months, in my experiment of "what happens if I use agents to develop a Free Software tool I want?", the market has gone from being entirely reasonable to pretty much unjustifiable from a price point of view.


  1. As I understand it, the $39 gets you almost twice that value in "AI credits", so the base allotment plus the flex allotment would cover what I've used. ↩

  2. That's not even the main reason to be concerned about a switch to Cursor. ↩