Posts tagged with "GitHub"

GitHub PR reviews broken

2 min read; 12 GFI

Late on last week I was doing a PR review at work and noticed that, for some odd reason, the author of the PR seemed to have absolutely nuked all of the indentation in the code. While not a problem given the nature of the files I was reviewing, I wasn't happy with their apparent disregard for style and good practice, and was about to leave a remark and a request for changes. But something seemed off. So I did a refresh of the page and... everything fell into place.

Weird.

Since then I've seen the issue on multiple machines. To be fair, each time it's been in Safari, and each time I've been busy with something else so haven't had the chance to really dive into it. But given it's suddenly cropped up, at the same time, on multiple machines, with nothing else changing, it feels like something on the GitHub side of things.

Broken code review

Perhaps I'm letting a bit of bias creep in here, but I feel like this sort of thing is happening more and more on GitHub. It's not that long back since social previews suddenly broke, for example. It's hard to shake the idea that changes are being made without regard to comprehensive testing, and likely without regard to how things connect.

Now, at this point, it would be easy to reach for the "well they're obviously using agents to do most of the work" argument -- and I'm sure plenty of people would -- but that doesn't quite fit with my experience. Having experimented with such tools for a good chunk of this year now, both for personal and, more recently, professional projects, I've generally found that such tooling easily helps with catching such issues.

Plenty of times now, when using something like Antigravity or Claude Code to work on some code, I've found that with reasonable care (you know: the sort of care you'd put into your work anyway) you can quickly and easily uncover connections and knock-on effects you might not have immediately noticed. Moreover, if LLMs are useful for anything when it comes to coding, it's for writing tests1. With that in mind you should be able to reasonably expect the number of silly bugs to go down.

Unless, of course, there's no human in the loop anywhere, or the human in the loop lacks adequate training and experience, or, I guess, they simply lack the ability to give a shit.

I wonder when this particular issue will get fixed? I should probably go and see if it's reported in the GitHub forums anywhere. I know for sure that there's little point in actually reporting it as a bug; my experiences with that in the past haven't been great, and the GitHub subreddit has seen enough stories of people getting nowhere.


  1. Arguably they're a little too good at it to the point of coming round the other side and doing badly again, if you don't keep an eye on things. 

next-gh-pr.el v1.1.0

1 min read; 9 GFI

A quick little update to next-gh-pr.el. Since writing the first version I've found it to be really useful, but I've also bumped into one small issue. Sometimes I'll create a draft PR before I remember to start the changelog entry, and so then I want to insert the current PR link rather than the next one.

Now, sure, I can just go and copy the URL and create the link in the changelog, but where's the fun in that when I can solve the problem in Emacs Lisp? So, with this in mind, I've just updated the package so that, with a prefix argument to the command, it will include a link for the latest PR rather than for the next one.

This does, of course, make the name a little less correct, but I'm not going to rename the package or the command for this one minor difference in intent.

GitHub social preview is fixed

1 min read; 12 GFI

Five days after I first noticed it, the ability to upload a social preview for a repository has been fixed.

Rogallo with an updated social preview

So now I can finally update the preview for Rogallo again.

From what I can see it took a couple or so threads in the community forums to get this issue noticed, and at least one person in those threads said how they'd initially raised a ticket to report it as a bug and had been brushed off and told to go to the community, as if it was something they were doing wrong rather than reporting a genuine issue.

This has been my experience in the past at least once. I forget the actual issue now, but I remember stumbling into a problem, being a good user and reporting the bug, along with details on how to reproduce, etc., and having the ticket closed and being brushed off with some vague and unhelpful reply. My recollection is that I then found a thread or two where others were talking about the problem. Eventually it was acknowledged and fixed.

It's hard not to feel like such an approach is a deliberate policy. It feels like their front-line support is now a shield that deflects problems to a place where community triage takes place.

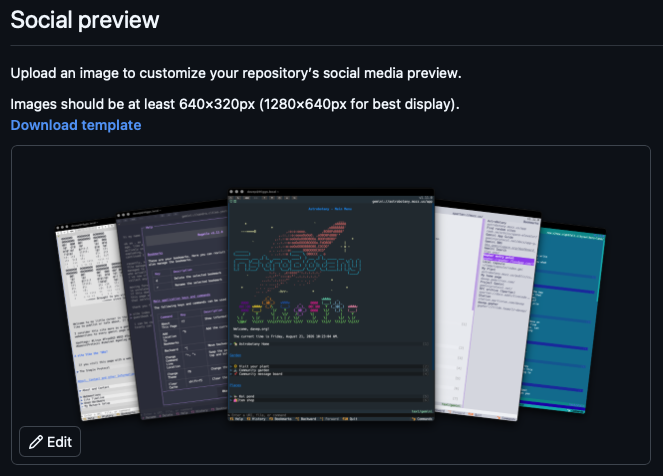
GitHub social preview is broken

2 min read; 7 GFI

Earlier today, now that Rogallo has matured a fair bit, I thought I'd update the banner image and, in doing so, refresh the "social preview" for the repository. This is easy enough, and something I've done plenty of times with plenty of projects. You just go into the general settings and upload a new image.

So, I faffed in Pixelmator Pro for a short while, got the new banner going, and then uploaded it. Weirdly, it didn't preview. I was just left with a blank rectangle.

Borked social preview on GitHub

I tried a couple more times... nothing. I then tested the repository itself with an online "social card" checking tool and, unsurprisingly, an image was set but it was a broken image.

Initially, I was entertaining the idea that I'd somehow done something silly, but really it's something hard to get wrong. A little bit of searching shows that it's not just me, with not one but two reports showing up.

It's things like this that bother me most when using GitHub (or any other large service). Sure, the big outages are bad, but with them you know they're being actively worked on, they're something that's going to be getting constant attention until they're resolved. Moreover, those sorts of issues generally suggest a scale problem1. These little bugs, though, suggest a lack of attention to detail, a lack of proper testing, a lack of care about the product as a whole.

It's not even the first time in the last couple of weeks that I've run into something like this. The other day I wanted to convert an issue into a discussion -- a feature I've used so many times before. This time... nope. Just didn't work. I forget exactly at what point it failed; I think the dialog popped up and then disappeared. Whatever the now-forgotten detail of the failure, the issue was that a long-standing, reliable feature just stopped working.

Again: big outages can be annoying, but in those cases I tend to just go off and do something else, either at my keyboard or, shockingly, away from it. By the time I get back into the office it'll be sorted. These little things... who knows when they'll be fixed?

Perhaps this bit-rot is a result of the panicked fixes to those big-bang problems?


  1. Yes, of their own design. But still... 

Recently I found - 4

1 min read; 7 GFI

Introduction

An occasional collection of things I've recently found on the Internet and added to my bookmarks.

This blog is written in English

Yeah, it's okay to write in your own voice, and for yourself. Weird, huh?

GitFut

Got to love a stupid GitHub-based profile rating tool.

Lisp hax

Lots of really useful Lisp code. Hours of great reading.

Very Average Prototypes

Interesting article about some of the downsides of working with AI to create code. Says a few things I've also been saying about my journey with BlogMore.

GTA2js

GTA2. On the web.

Half-Life 2 on the web

Half-Life 2. With follow-ups. On the web.

The AI Hype Reckoning Is Upon Us

Good article about the gulf that does seem to exist between the hype around AI in business, and the actual benefits.

Mastodon, The Only Good Choice

Good article about what Mastodon delivers if you enjoy social media.

Please delete your repository

If you had never opened this repository, there is a 21% chance that we would have already cured cancer. Let that sink in.

I don't care if it's totally made up, it made me chuckle.

CSS-DOS

An entire PC built in CSS.

Human Emacs

I feel like this project is jumping the gun quite a bit, but I also appreciate that it exists. I did also see someone say the other day that it was worth running with anyway to "get away from RMS". Which is fair I guess.

Mastodon Most Followed

Because it's all about being popular...

Web Flight

A flight simulator, on the web. What's not to like?

Perfect to mess with during those boring Teams calls...

A Road to Lisp: Which Lisp

Good review of all the Lisp options you have available to you today.

A24 got embroiled in copyright strikes against online creations related to the Backrooms. People, unsurprisingly, got very angry. The issue seems solved, for the moment, but it says a lot about capitalist appropriation of mass-created popular culture.

ZeroVer

Fantastic list of well-known and popular applications that seem too afraid to ever evolve beyond v0.x.

AI Mania Is Eviscerating Global Decision-Making

I feel this so much. I wish the people who need to read this would read this.

Copyright Nvidia

1 min read; 7 GFI

I've been trying, on and off, copilot.el. I'm kind of 50/50 on it most of the time. Sometimes it seems to really understand the code around what I'm working on and does a good job of helping complete the thing I'm about to type; other times it makes wild predictions that just annoy me and get in the way.

It's interesting to experiment with though.

But, just now, I saw something new1. I'd just started a fresh file and run funhead. That means that what had been typed into my buffer was:

##############################################################################
# _

and my cursor was sat where you see the _ above. Then Copilot made a suggestion:

Copilot doing its thing

Like, sure, we all know that this is what can happen, but damn. Still, of all the companies involved with or adjacent to AI, I guess they're the ones to care the least.


  1. To me, I know others have seen this sort of thing before. 

New GitHub Copilot billing is popular

1 min read; 8 GFI

So today is the day, today is when GitHub Copilot swaps to its new billing system. Watching the relevant subreddit suggests this might not be popular.

Some folk think it isn't the smartest move.

Not a good choice

Some don't feel too friendly towards it any more.

Friendship ended

It looks like some of those friendships have lasted a while.

2021-2026

Some saw the opportunity to create content out of the situation.

A cancellation video

Some have figured out that the thing that costs money, costs money.

It is too expensive

Someone used up half their monthly allowance on just 8 requests.

Half used after 8 requests

Although, of course, there's always someone who has to do it better.

Half after 1 request

To be fair though, at least one person loves the new system.

Love the new system

As for my subscription, which came about after I initially experimented with free access to the tool, I've not actually cancelled yet, but I can't see me making use of it much more. I might try a couple of prompts with it, along the lines of what I was doing while working on BlogMore, just to get a feel for how different the usage is now.

Meanwhile, though, I've found that I'm getting on a lot better with Antigravity and getting the bits done I want to do. I suspect this is how I'll keep tinkering with BlogMore, until Google come to their senses anyway.

Reviewing the cost of BlogMore

3 min read; 8 GFI

Now that we're near the end of the free or cheap GitHub Copilot party, I thought it might be interesting to look at how much BlogMore has "cost" me to build, and what it would have cost under the proposed new pricing structure that is coming in next month. While I've looked at the comparison for last month, I've not looked at the whole period I've been seriously using it.

So, for this review, I'm looking at all the data I can pull out of GitHub for the months of February, March, April and May of this year. Development of BlogMore started back in February and, while it hasn't been 100% the cause of my use of Copilot premium requests, it's been almost all of it. For the purposes of this review I'm just going to take the approach that all I worked on was BlogMore.

Remember that, even when I had free access, I had a maximum of 300 premium requests per month. Once I lost free access I had the same number of requests for $10 a month.

Here's how those months broke down:

MonthPaidPremium Requests%agePredicted Price
February$0.0024983%$21.67
March$10.0014047%$56.38
April$10.0013244%$53.77
May$10.003411%$53.69
Total:$30.0055546%$185.51

So, give or take, something that I've actually spent $30.00 on could have, at best, cost me $185.51. That's assuming that the "cost" of the models I was using stays the same. You can see that the costs have risen already in that the predicted price from February, where I used 83% of my premium requests, is a touch under half the cost for this month, where I've used just 11%. From what I can see in the raw data, it's down to some models suddenly being considered more expensive (perhaps I was doing something that just consumed more tokens, I'm not 100% sure if I'm honest, but I don't recall anything that seemed like harder work).

Who knows what the real costs will be come June.

Now, technically, the actual cost under the new regime could or should be $156, because it would be 4 lots of the $39.00/month plan, which would better cover that use1. Again though, that's assuming the actual cost of using whatever models remains pretty stable. It also assumes that I'd want to spend that much each month, and that I would be correctly anticipating that I'd need that much.

Also, this isn't even the total cost of getting this project done. As I've written recently: I've been using Gemini CLI more this month, and while the usage there is a flat cost, until now, that's changing too.

Now, of course, these aren't the only games in town. I could "go to the source" and just get a sub for Claude Code or something, and as Tim pointed out over in the Fediverse, something like Cursor does a lot of this and is just $20/month. Which all sounds fine, but what happens when those fleeing GitHub Copilot or Gemini CLI/Antigravity head over to something like Cursor? Is it sensible to expect the pricing to stay the same2?

I guess, at this point, I'm just mulling over the same issue time and again, but from different angles. It does seem clear to me, though, that in less than 4 months, in my experiment of "what happens if I use agents to develop a Free Software tool I want?", the market has gone from being entirely reasonable to pretty much unjustifiable from a price point of view.


  1. As I understand it, the $39 gets you almost twice that value in "AI credits", so the base allotment plus the flex allotment would cover what I've used. 

  2. That's not even the main reason to be concerned about a switch to Cursor

next-gh-pr.el v1.0.0

1 min read; 12 GFI

Pretty much every project that I actively maintain on my GitHub account has a change log of some description. For a long time now, whenever I add a new entry to the log, I'll include a link to the PR that implements that change. Inevitably, this results in me adding the ChangeLog entry, creating the PR, then doing a follow-up change and commit now that I know the PR number, which allows me to add the link.

So I've created next-gh-pr.el to save me just a little time and let me be just a little more lazy. Inside it I've currently got a next-gh-pr-insert-markdown-link command which, when run, as you might imagine, inserts a link to the next likely PR URL as Markdown.

Working out the next URL is simple enough: get the latest issue and PR number, take whichever is the highest, and add 1. There is the wrinkle that discussions also cause this number to bump, and getting the latest discussion number is a little extra faff that I can't be bothered with right now, but my projects very seldom have discussions taking place anyway.

Gemini CLI vs GitHub Copilot (the result)

4 min read; 11 GFI

Following on from this morning's initial experiment, I think I'm settling on a winner. Rather than be annoying and have you scroll to the bottom to find out: it's Gemini CLI. Here's how I found the process played out, and why I'm settling for one over the other.


Gemini CLI

Initially this was an absolute mess. After letting it initially work on the problem, the resulting code didn't even really run. The first go, and the three follow-up prompt/result cycles that followed, all resulted in code that had runtime errors. I'm pretty sure it didn't even bother to try and do any adequate testing. This is odd given I've generally seen it do an okay job when it comes to writing and running tests.

Once I had the code in a stable state, with all type checking, linting and testing passing, it still didn't work. No matter how I tried to use the new facility it just didn't make a difference. No images were optimised. In the end I dived into the code, with the help of its attempt at debugging (it added print calls to try and get to the bottom of things -- how very human!), diagnosed what I thought was the issue (it was looking in the wrong location for the files to optimise), told it my hypothesis and let it check if I was right. It concluded I was and fixed the problem.

Since then I've had a working implementation of the initial plan.

Once that was in place it's been a pretty smooth journey. I've asked it questions about the implementation, had my concerns set to rest, had some concerns addressed and fixed, improved some things here and there, added new features, etc.

All of this has left me with 18% of my daily quota used up. While I think this is the highest I've ever got while using Gemini CLI, it still feels like I got a lot of things done for not a lot of quota use.

GitHub Copilot

Initially I thought this had managed to one-shot the problem. Once it had finished its initial work the code ran without incident and produced all the optimised files. Or so I thought. Doing a little more testing, though, it became clear it was only optimising a subset of the images and it didn't seem to be producing the actual HTML to use the images.

On top of this it didn't even follow the full plan that was laid out in the issue it was assigned. For example: once I'd got it doing the main part of the work, it became apparent that it had pretty much ignored the whole idea of using a cache to speed this process up. I had to remind it to do this.

At one point I switched from the in-PR web interaction with Copilot, and used the local CLI instead. When I ran that up it warned me that I was already 50% of the way through some sort of rate limit and this wouldn't reset for another 3 hours. I think I was about 40 minutes into letting it try and do the work at this point.

After a bit more testing and follow-up prompts, I got to a point where I had something that looked like it was working; albeit in a slightly different way from how Gemini CLI did it (the Copilot approach was writing the optimised images out to the extras directory, mixing them in with my own images; Gemini opted for having a separate directory for optimised images within the static hierarchy).


At this point I will admit to not having carefully reviewed the code of either agent; that's a job still to do. But while Gemini got off to a very rocky start, with a bit of guidance it seemed to arrive at an implementation I'm happy with, and one that seems to be working as intended. While it didn't anticipate all the edge cases, when I asked about them it easily found and implemented solutions for them. Moreover, the fact that I could do all of this and confidently know the "cost" made a huge difference. Copilot seems to generally approach this like a quota or rate limit should be a lovely surprise that will destroy your flow; Gemini has it there and in front of you, all the time.

As for the general idea that I'm working on: I think I'm going to implement it. Weirdly I'm slightly nervous about building the blog such that it won't be using the images I created, but I also recognise that that's a little irrational. Meanwhile I'm very curious about the impact this might have on the PageSpeed measurement of the blog. While it's far from horrific, image size optimisation and size declaration seem to be fairly high on the things that are impacting the performance score (currently sat at 89 for the front page of the blog, as I type this).

The other thing that gives me pause for thought about merging this in, and then subsequently using it, is that I've just finished migrating all images to webp, and so saving a lot of space in the built version of the blog. Generating all the responsive sizes of the images eats that up again. With this feature off, the built version of the blog stands at about 84MB; with it on, this rises to 133MB. That extra 49MB more than eats up the 24MB saving I made earlier.

On the other hand: storage is a thing for GitHub to worry about, what I'm worrying about here, and aiming to improve, is the reader's experience.

I'm going to sit on this for a short while and play around with it, at least until I get impatient and say "what the hell" and run with it.