Posts tagged with "Lisp"

blogmore.el v5.0.0

3 min read; 10 GFI

When I released blogmore.el v4.7.0 yesterday I finished off by saying that it was my intention, at some point, to rework the frontmatter-handling code so that it did proper YAML parsing. As often happens with these sorts of things, "some point" ended up being that evening.

I've rewritten everything to do with handling properties in the frontmatter so that it now uses yaml.el. This has a number of knock-on effects. The first and most obvious effect is that anything that is a list/array in the frontmatter is actually properly treated as a list. A good example here is tags. Now you can have your tags look like:

tags: [BlogMore, Emacs, "Emacs Lisp", Lisp, "blogmore.el", coding]

or:

tags:
  - BlogMore
  - Emacs
  - Emacs Lisp
  - Lisp
  - blogmore.el
  - coding

and blogmore.el will still handle things fine. The same holds for series too.

It should be noted, however, that because I'm now using actual YAML serialisation code, most other forms of a list will all end up being transformed into this kind:

tags: [BlogMore, Emacs, "Emacs Lisp", Lisp, "blogmore.el", coding]

So if you have a bare list:

tags: BlogMore, Emacs, "Emacs Lisp", Lisp, "blogmore.el", coding

and you make an edit to the tags via blogmore.el, it will end up as the version enclosed in []. BlogMore itself supports all three versions so this works fine.

There is a breaking change here too, which in part explains the reason I bumped the version to 5.0.0: because series can now be treated as a list I've removed the blogmore-set-series command and instead replaced it with blogmore-add-series and blogmore-remove-series. Both can of course be found in the transient menu.

Another big change in this release is the way that existing values are loaded up from your blog. Previously, when you went to add a category, tag or series, blogmore.el would use ripgrep (or a combination of find and grep if rg wasn't available) to pull out values to help populate a completion list. This worked fine as long as a) the frontmatter property was all on one line and b) the body of a post didn't contain something that looked like a frontmatter property. With this release of blogmore.el I've dropped this approach in favour of calling blogmore itself and using the dump command to get the actual lists of categories, tags and series.

This does mean that BlogMore needs to be installed in a location where blogmore.el can see it, and to help with this I've added a new defcustom called blogmore-command. By default this is set to call whatever version of blogmore can be found in your exec-path; if this results in unexpected behaviour you can set blogmore-command to point to a specific copy of blogmore.

There is, however, a small downside to this beneficial1 approach: calling on blogmore and parsing all posts to get the values is generally going to be slower. With this in mind I've built in a cache for these values. The first time you load up the categories, tags or series, the values are held on to so that subsequent prompts are instantaneous (meaning there is no further call to blogmore). To ensure this doesn't confuse things, when you switch blog (blogmore-work-on) the caches are cleared. In the unlikely event that there is a problem with this approach, I've also added a blogmore-clear-caches command to force the clearing of the caches.

There are some other small QoL changes under the hood and also to the interface. I've moved some things around in the transient menu, and also ensured that a couple of options are better-disabled depending on the context.
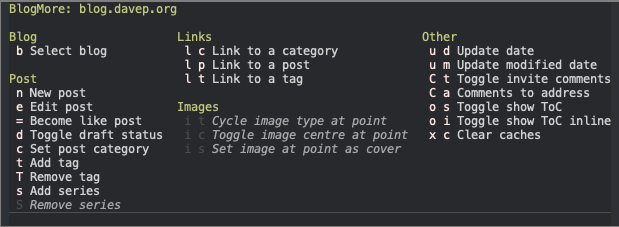
The current menu

All of this makes the package even more robust. Something that started as a quick hack back in March has turned into a tool I heavily lean on. Hopefully, for anyone who might happen to use BlogMore and GNU Emacs, it'll be a useful daily-driver for them too.


  1. The benefits being: only values in frontmatter appear, inconsistent casing is cleaned up, etc. ↩
blogmore.el v4.7.0

1 min read; 9 GFI

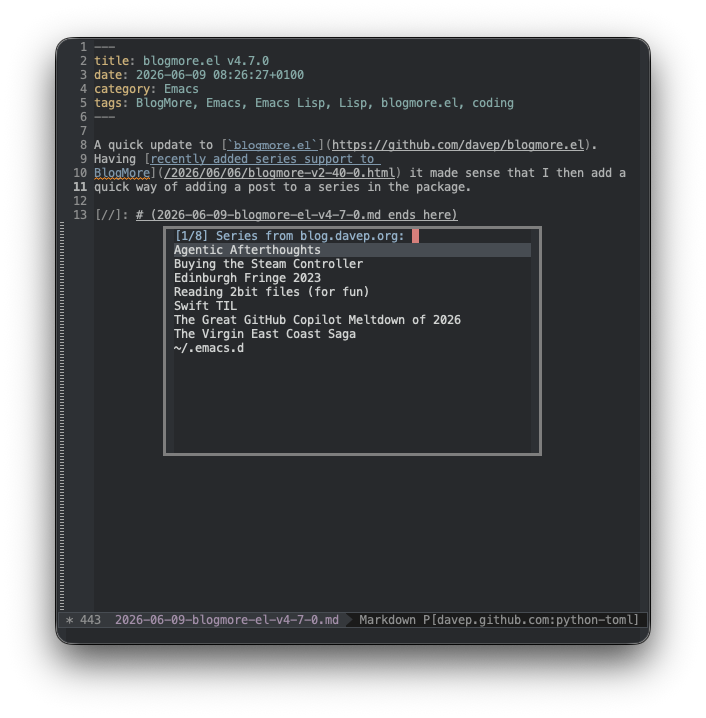
A quick update to blogmore.el. Having recently added series support to BlogMore it made sense that I then add a quick way of adding a post to a series in the package.

Selecting a series

You can, of course, set a new one too, but the idea here (as with categories and tags) is that you can quickly find back an existing series and add the current post to it.

Also, as with tags, the expectation is that either a single series is being used, or if more than one series is in play for a post they'll be listed as a comma-separated list. The issue here is that while BlogMore supports this:

series:
  - Some series of posts
  - Some other series of posts
  - Yet another series of posts

the frontmatter-handling code in blogmore.el isn't very sophisticated at all; it doesn't actually handle it as actual YAML, instead just treating it as a set of key/value pairs separated by a colon.

At some point soon I want to give blogmore.el a revamp and base all of the frontmatter-handling code on something like yaml.el. I did do some experimenting last night to drop it in and handle proper lists. It worked well enough, but I abandoned the work as I realised I really wanted to start again from scratch and build blogmore.el from the bottom up using that package.

Some time soon...

blogmore.el v4.6.0

1 min read; 11 GFI

After adding floating and inline tables of contents in BlogMore the other day, it was time to update blogmore.el to include commands to toggle the related frontmatter.

So, with the release of blogmore.el v4.6.0, two new commands are now available:

  • blogmore-toggle-show-toc toggles the show_toc frontmatter property.
  • blogmore-toggle-show-toc-inline toggles the show_toc_inline frontmatter property.

Both have also been added to the transient menu so they're easy to discover and use.

next-gh-pr.el v1.0.0

1 min read; 12 GFI

Pretty much every project that I actively maintain on my GitHub account has a change log of some description. For a long time now, whenever I add a new entry to the log, I'll include a link to the PR that implements that change. Inevitably, this results in me adding the ChangeLog entry, creating the PR, then doing a follow-up change and commit now that I know the PR number, which allows me to add the link.

So I've created next-gh-pr.el to save me just a little time and let me be just a little more lazy. Inside it I've currently got a next-gh-pr-insert-markdown-link command which, when run, as you might imagine, inserts a link to the next likely PR URL as Markdown.

Working out the next URL is simple enough: get the latest issue and PR number, take whichever is the highest, and add 1. There is the wrinkle that discussions also cause this number to bump, and getting the latest discussion number is a little extra faff that I can't be bothered with right now, but my projects very seldom have discussions taking place anyway.

blogmore.el v4.5.0

1 min read; 6 GFI

Carrying on with the theme of being lazy while editing posts, I've released blogmore.el v4.5.0. This version adds blogmore-set-as-cover. With this, if you place point on a line that is an image and run the command, it is set as the cover for the post.

Sure, it's not like it's hard to copy, move, insert a new line, type cover: and then paste the text, but this is faster and more accurate.

And I'm lazy.

And I like hacking on Emacs Lisp that makes my workflow flow faster.

blogmore.el v4.4.0

1 min read; 8 GFI

I've released an update to blogmore.el, my Emacs package that helps me out when writing this blog. I've added two commands to this version which help me be lazier than ever.

The first is blogmore-become-like. When run, this prompts for another post and, once selected, it sets this post's category and tags to be the same as the other one. I added this because I'm often writing an occasional series of posts that are all about the same project, and so I always find myself copying and pasting those frontmatter properties from another post.

The second command I've added is blogmore-toggle-image-centre. Built into BlogMore is a little bit of styling that will ensure an image is placed in the centre of the page, if the URL for the image has #centre on the end. This means that, for most images I add, I have to go and edit the URL to add that. Now I can just run a single command when the cursor is on an image and it'll add (or remove, if it's already there) that styling hint.

In both cases, I've added the commands to the transient menu too.

blogmore.el v4.3.0

1 min read; 8 GFI

After adding the email comment invite facility to BlogMore it only made sense that I add some commands to blogmore.el to make it easier to edit the front matter that can help drive that feature.

So... I've released v4.3.0 of blogmore.el that adds two new commands:

  • blogmore-toggle-invite-comments -- toggles the comment invitation property
  • blogmore-invite-comments-to -- makes it easy to set, edit or remove the email address to use when making the invite

I've also added the two commands to the transient menu, using C-t for the former and C-a for the latter.

kbdify.el v1.0.0

1 min read; 11 GFI

When I'm writing documentation in Markdown I like, where possible, to mark up keys with the <kbd> tag. This was the reason for one of the updates to BlogMore: I'd not done any good default markup for <kbd> and the moment I realised, I knew I had to fix it.

Now that I'm writing more on this blog, and especially about coding, I'm mentioning keys pretty often (even more so given I'm doing a lot of tidying up of my Emacs Lisp packages). The thing is though: I find having to type out <kbd> and </kbd> kind of tedious, and it's something I mistype from time to time. I guess I could use some sort of HTML tag inserting tool or whatever, but I got to thinking that it would be handy if I could point an Emacs command at a particular sequence in a buffer and have it mark up the whole thing.

This resulted in a small bit of code I'm calling kbdify.el. It's pretty simple, if point is sat on some text that looks like this:

C-M-S-s-<up>

and I run kbdify I get this:

<kbd>C</kbd>-<kbd>M</kbd>-<kbd>S</kbd>-<kbd>s</kbd>-<kbd>&lt;up&gt;</kbd>

The result rendering as C-M-S-s-<up>.

I could probably take it a bit further, have it optionally work on a region and stuff like that, but even in its current simplistic form it's going to be loads quicker and a lot more accurate and will probably perfectly cover 99% of the times I need it. There is the issue that it's not going to handle something like M-x some-command RET in the way I might like, but then again some-command isn't a key. Like, does it make more sense to have:

M-x some-command RET

anyway? Personally I think this:

M-x some-command RET

probably makes more sense.

I think I'm good for now.

itch.el v1.3.0

1 min read; 11 GFI

When I'm working in Emacs I use the *scratch* buffer quite a bit. I find it especially useful if I'm working on some Emacs Lisp code, but I also find it handy as a place to drop something I want to retrieve soon, or a quick note that I want to refer back to soon; sometimes I even paste some text there and copy it back just to strip the formatting from it before using it elsewhere1.

Because of this, for a long time, I carried a little function around that I had bound to M-s to quickly take me to the *scratch* buffer. Then, I think around the time I did the follow-up revamp of my Emacs configuration, I turned it into a little package for my own use called itch.el.

The command (itch-scratch-buffer) is simple enough: run it and I get switched to my *scratch* buffer. If I run it with a prefix argument it switches to *scratch* and resets the content back to the initial-scratch-message.

More recently I've found that I'm wanting a scratch buffer that is for writing Markdown. Like many folk I use it a lot for documentation, and of course I also use it for this blog. I also use it heavily for keeping notes in Obsidian2. So, often, I find myself switching to a temporary buffer (*foo* or something), setting it to markdown-mode, and then writing what I need.

So yesterday I finally cracked and added itch-markdown-scratch-buffer. It's just like itch-scratch-buffer, only it creates a *scratch: Markdown* buffer, using the same clear-if-prefix rule.

So now I've got this bound to M-S-s and I can faff around just a little less when I want a Markdown scratchpad.


  1. On macOS at least, I find the "paste without formatting" support of some applications to be really inconsistent; a quick layover in the *scratch* buffer does the trick every time. ↩

  2. Yes, I know, I should be using Org, but sadly it's just never clicked for me, and I also find good syncing and having a consistent application on mobile and desktop are important. ↩