Posts tagged with "PyPI"

BlogMore v2.20.0

3 min read; 12 GFI

I've just released BlogMore v2.20.0. There are five main changes in this release, and a lot of changes under the hood.

First, the under-the-hood stuff: while this isn't going to make a difference to anyone using BlogMore (at least it shouldn't make a difference -- if it does that's a bug that deserves reporting), the main site generation code has had a lot of work done on it to break it up. The motivation for this is to make the code easier to maintain, and to try and steer it in a direction closer to how I'd have laid things out had I written it by hand. The outcome of this is that, where the generator was over 2,000 lines of code in a single file, it's now a lot more modular and easier to follow.

Some other internals have been cleaned up too. Generally I've had a period of reviewing some of the code and reducing obvious duplication of effort, that sort of thing.

Now for the visible changes and enhancements in this release:

Improved word counts

Until now the word counting (and so the reading time calculations) were done by stripping most of the Markdown and HTML markup from the Markdown source. I wasn't too keen on this approach given that the codebase had a method of turning Markdown into plain text. So in this release the regex-based cleanup code is gone and word counts (and so reading times) use the same Markdown to plain text pipeline as anything else that needs to work on plain text.

Fixed a word count and reading time disparity

It was possible, in the stats page, to have one post appear to have the lowest or highest word count, but to not have the lowest or highest reading time. This was because reading times are always calculated to the minute and so there could be a disparity due to this rounding. The calculation of those stats now takes this into account.

Added an optional title to the socials

The socials setting in the configuration file has had an optional title property added for each entry. Until now the tooltip for an entry would be whatever the site was set to. Generally this works but if you have two or more accounts on the same site, or if you want to use a site value for something different, there was no way of making the tooltip more descriptive.

As an example, currently it's not possible to support Codeberg as a site. On the other hand git is available so it can be used as a substitute icon. The problem is, with this:

- site: git
  url: https://codeberg.org/davep

the tooltip will just say "git". With this update you can do this:

- site: git
  title: Codeberg
  url: https://codeberg.org/davep

and the tooltip will say "Codeberg".

As mentioned: this is optional. If there is no title the previous behaviour still applies.

Wall-clock time measurement

Yesterday, Andy posted about BlogMore's performance with respect to the different optional features. It's something I haven't really considered yet (possibly in part because this blog isn't anywhere near as big as his), but could be a good source of tinkering in the near future. His work to test the different parts of the tool did get me thinking though: it would be neat to know how long each part of the generation process takes.

So now, when a site is generated (either when using build or serve), the time of each step is printed, as is the overall generation time.

Markdown in HTML support

Yesterday I noticed that, on one of my posts, what had been written as a simple caption for an image wasn't rendering as it used to. The actual content of the Markdown source for the post contained this:

<center>
*(Yes, the tin was once mine and was once full; the early 90s were a
different time)*
</center>

While the text was centred, the raw Markdown was left in place (it should have been italic text). The reason for this is that BlogMore had never enabled Markdown-in-HTML support. So, as of this release, if the enclosing tag has markdown="1", any Markdown inside the tags will be parsed. This means the above becomes this:

<center markdown="1">
*(Yes, the tin was once mine and was once full; the early 90s were a
different time)*
</center>

I did think about doing something to turn it on by default (the fact that I didn't have such a "switch" in the post before suggests that Pelican did just always do this), but really I feel this approach is more flexible and less likely to result in unintended consequences.
BlogMore v2.19.0

1 min read; 10 GFI

While I'm messing around in the background of BlogMore, looking at the state of the code and looking for opportunities to clean it up, either by hand, or by pitting agent against agent, I've also been doing the odd little fix here and there.

I've just released BlogMore v2.19.0, which has a couple of fixes, and also a small improvement.

The first fix is something I noticed late on last week when I was sharing one of the archive pages from my blog with someone. I noticed that the preview that appeared didn't have the default blog image, nor did it have any sort of description. This should happen in that, on any page that isn't a post with a specific cover image or description, it should fall back to the blog's defaults. Turns out this logic was missing from things like the date-based archives, the category and tag archives, and a number of other parts of the generated output.

That's now fixed.

The second fix is to the recently-added backlinks feature. While reviewing the effect of something else I was working on, I specifically noticed that this post didn't have a backlink section at the bottom, despite the fact that it was linked to from this post. The cause seemed pretty clear: the fact that I had parentheses in the URL. My guess was that the regex that the link-finding code uses wasn't taking this sort of thing into account; my guess was right.

The final change in this release is that the per-build cache-busting feature has been extended to all the JavaScript files that are generated when building the site. Before it was mostly only applied to the main stylesheets and a couple of long-standing bits of JavaScript. Now it's added to the code that's used for search, the code-block support code, the graph, etc. This means that if there are any changes in those files between builds and deployments of a site, there's less chance of unexpected behaviour that needs a "clear the cache first" fix.

BlogMore v2.18.0

1 min read; 12 GFI

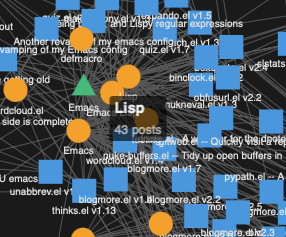
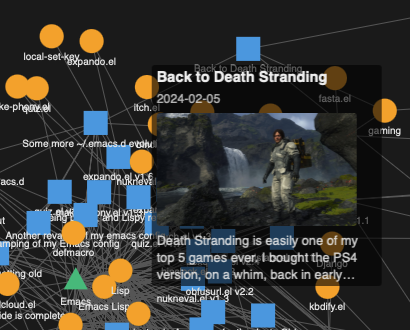
After releasing the graph view yesterday I got to thinking that it might be nice if the "tooltips" for the nodes in the graph were a little richer. Since we already know how many posts are within a category, or have a specific tag, it makes sense that those counts should be shown; posts themselves have descriptions available and some even have cover images that could be turned into thumbnails. Why not make use of all of that?

So I've made use of all of that. As mentioned, categories and tags simply show the count of posts related to them:

A tag tooltip in the graph

Posts will show the title, date, description and the cover image if available:

A post showing its tooltip

I'll admit that the transparency is a little distracting -- this comes from the library being used for the graph -- but I kind of like it. I'm going to roll with it now and see how I feel about it as time goes on. It's not like I expect a reader to read the post in the tooltip, it's an invitation to click through and read the actual post.

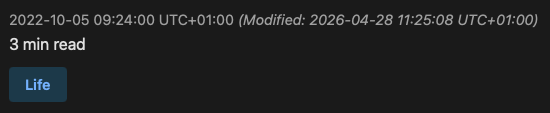
Another small change is something I've been meaning to address for a while. While BlogMore supports a modified time for a post it never shows it or uses it in any meaningful way. So now I've updated the way the time of a post is displayed so that, if there is a modified time, it's also shown:

Showing when a post was last modified

The final change came in as a request over on Mastodon. The wish being that there was an easy method, that didn't require the user spin out their own copy of a template just to do it, of changing the title of the backlinks section on a post from "References & Mentions" to something else. That seemed fair so I've introduced backlinks_title.

BlogMore v2.17.0

4 min read; 11 GFI

I did some more tinkering with BlogMore yesterday, adding two new features. The first is one I've been considering adding for a wee while now.

For a large part of the lifetime of this blog I used Disqus to provide a comments section on every post. It was, as you'd imagine for a small personal blog, a pretty quiet thing; I'd get the odd comment from time to time but it wasn't significant. This worked well for the longest time, until Disqus decided that they were going to force adverts into your pages if you were using the free tier. Now, I'm fine with paying for tools I use, but I wasn't using Disqus enough to make the cost worth it. I'm also not opposed to a bit of subtle advertising to help cover costs either.

What Disqus did wasn't subtle. It was far from subtle. It was a horror show of the worst kind of sleazy advertising you can imagine.

So I removed it and called it a day on comments.

After the work on BlogMore was well under way I did start thinking about this problem again. Given how BlogMore is constructed, anyone using it could override a template and include whatever they want; with this in mind I looked at static-site-friendly comment options but nothing really stood out. Every solution seemed to either heavily rely on a third party service (see above for possible problems), self-hosting such a service (spinning up hosts and web servers and databases and stuff is the antithesis of using a static site generator to get stuff done easily), or some hacky use of a social media platform or other discussion venue that would require the reader jump through hoops that really looks like "go away, I don't want to hear from you".

So I concluded that it just wasn't worth the effort and I've done nothing with it.

Meanwhile: on occasion I have had people just email me about a post. Good old email, like in the good old days of the Internet. I kind of liked that. In fact I really liked that. So over the weekend, after receiving just such an email the other day, I decided I'd add a feature to BlogMore that provided just that: an invitation to send an email at the end of every post.

The configuration file now has two new properties that support this. The first is invite_comments. This is a boolean value that simply turns on or off the feature. The second is invite_comments_to. This should be set to an email address that the reader will be invited to direct their comment or question or whatever.

I've made the latter a little smart, in that it's actually a template, so that you can control the email address used per-post. This could be great for filtering, etc. Examples could be:

  • blog-comment@example.com
  • blog-comment-{year}{month}{day}@example.com
  • {author}+comment@example.com

And so on. You get the idea.

Further to this there's also post frontmatter properties of the same name. In this case the frontmatter setting always overrides the configuration file setting, for that single post. Also the invite_comments_to frontmatter setting isn't a template -- it's being set for a single post so that didn't seem necessary. The point of the frontmatter is it gives the flexibility to turn the invite off for an individual post (or indeed turn it on if the global setting is for it to be off).

The effect of all of this is that, if the invitation setting is on and if there is an email address available, this little box will appear at the bottom of a post:

An invitation to send me an email

When the reader clicks on the link it should open their MUA of choice and pre-fill the to address, and should also pre-fill the subject with the title of the post they're emailing from.

The second addition is prompted by the final paragraph in the post announcing the previous release of BlogMore:

At some point in the future it might be interesting to take this even further and produce a map of interconnected posts; for now though I think this is enough.

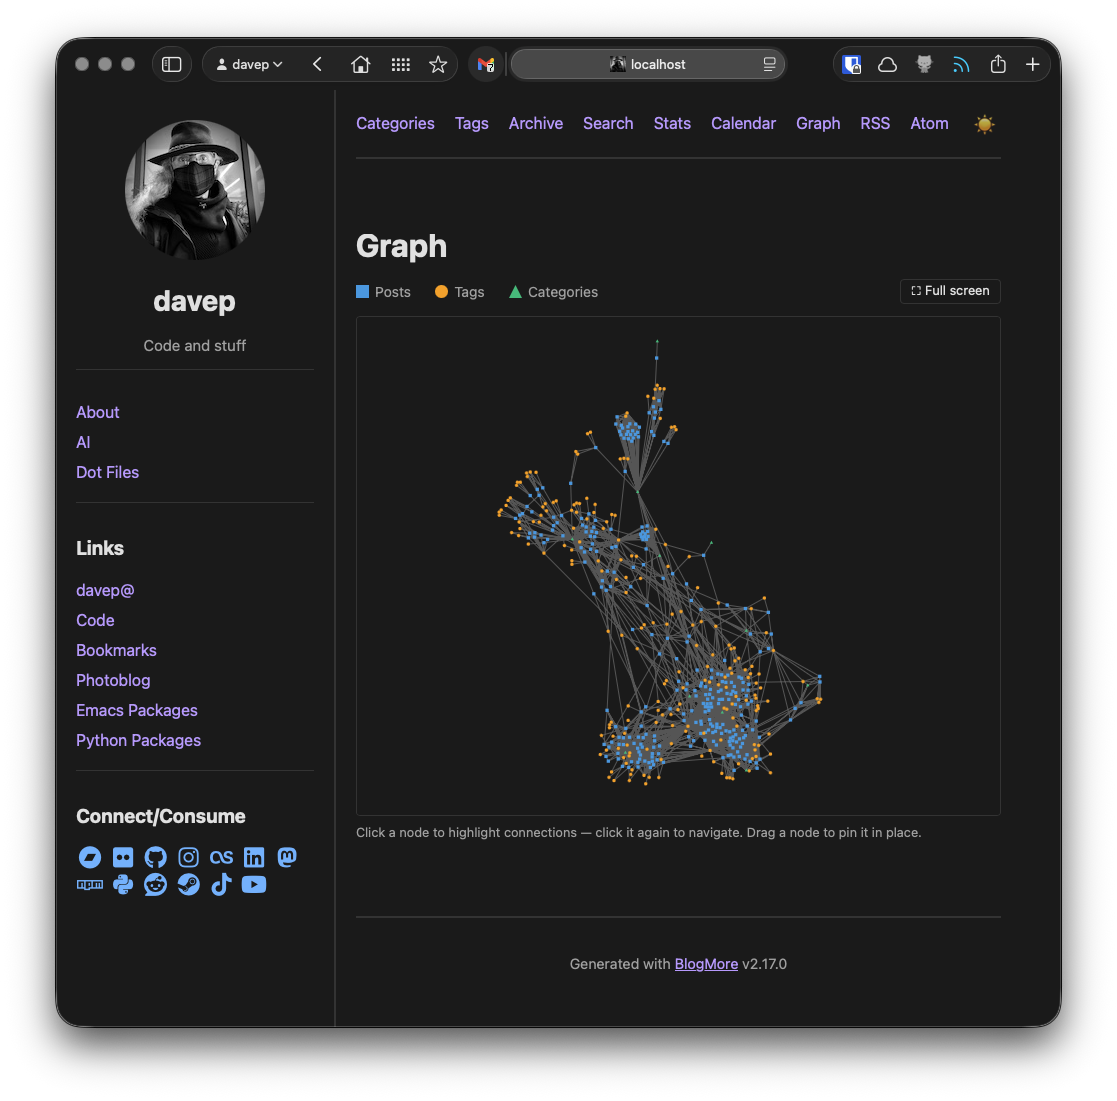
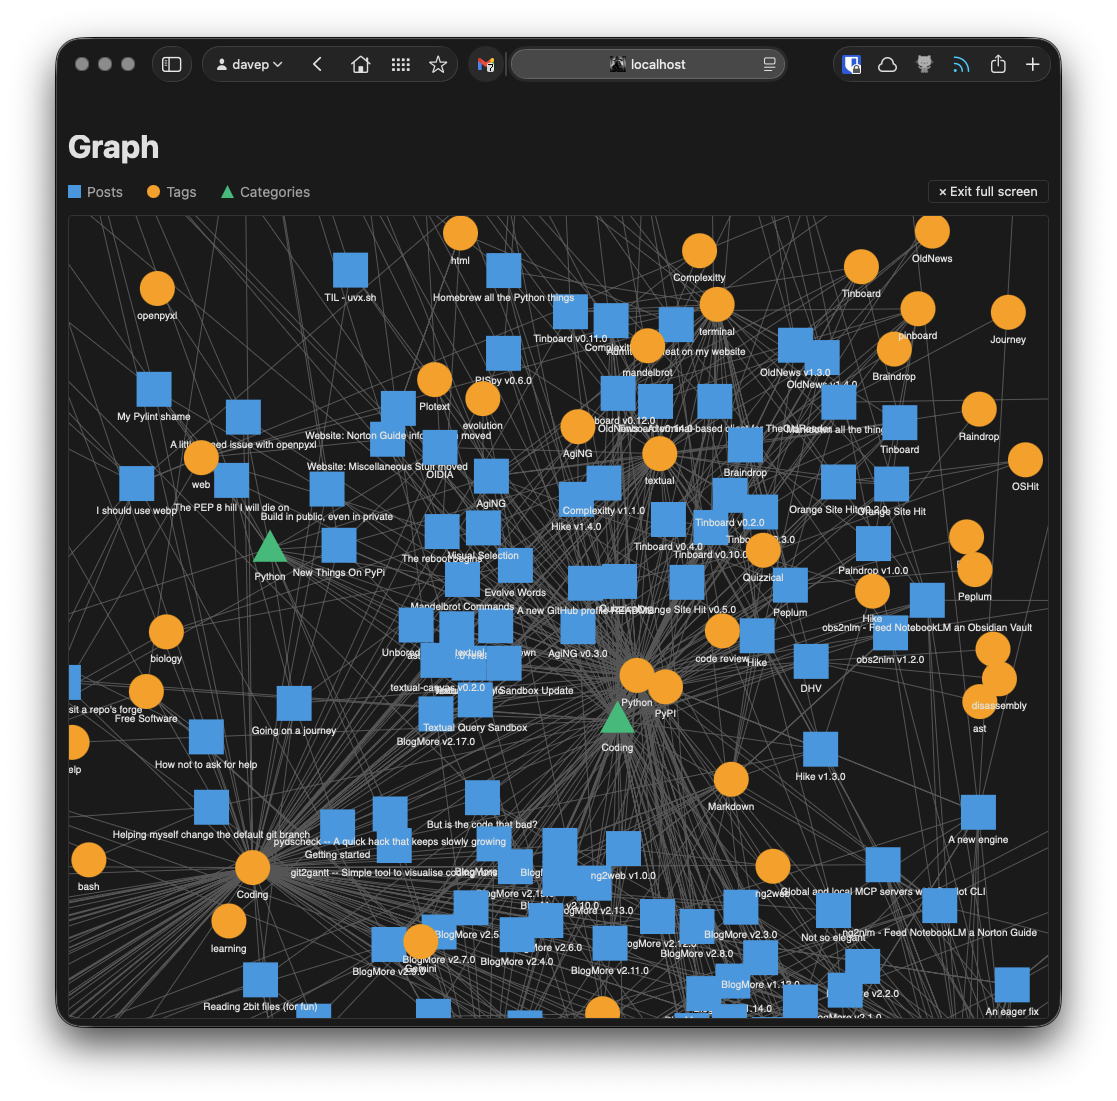
Apparently "some time in the future" was the following day; because that also got added while I was hacking on the sofa. There's a new --with-graph command line option, and with_graph configuration file setting, that adds a Graph page to the top "menu" of the blog. The result looks something like this:

Initial graph view

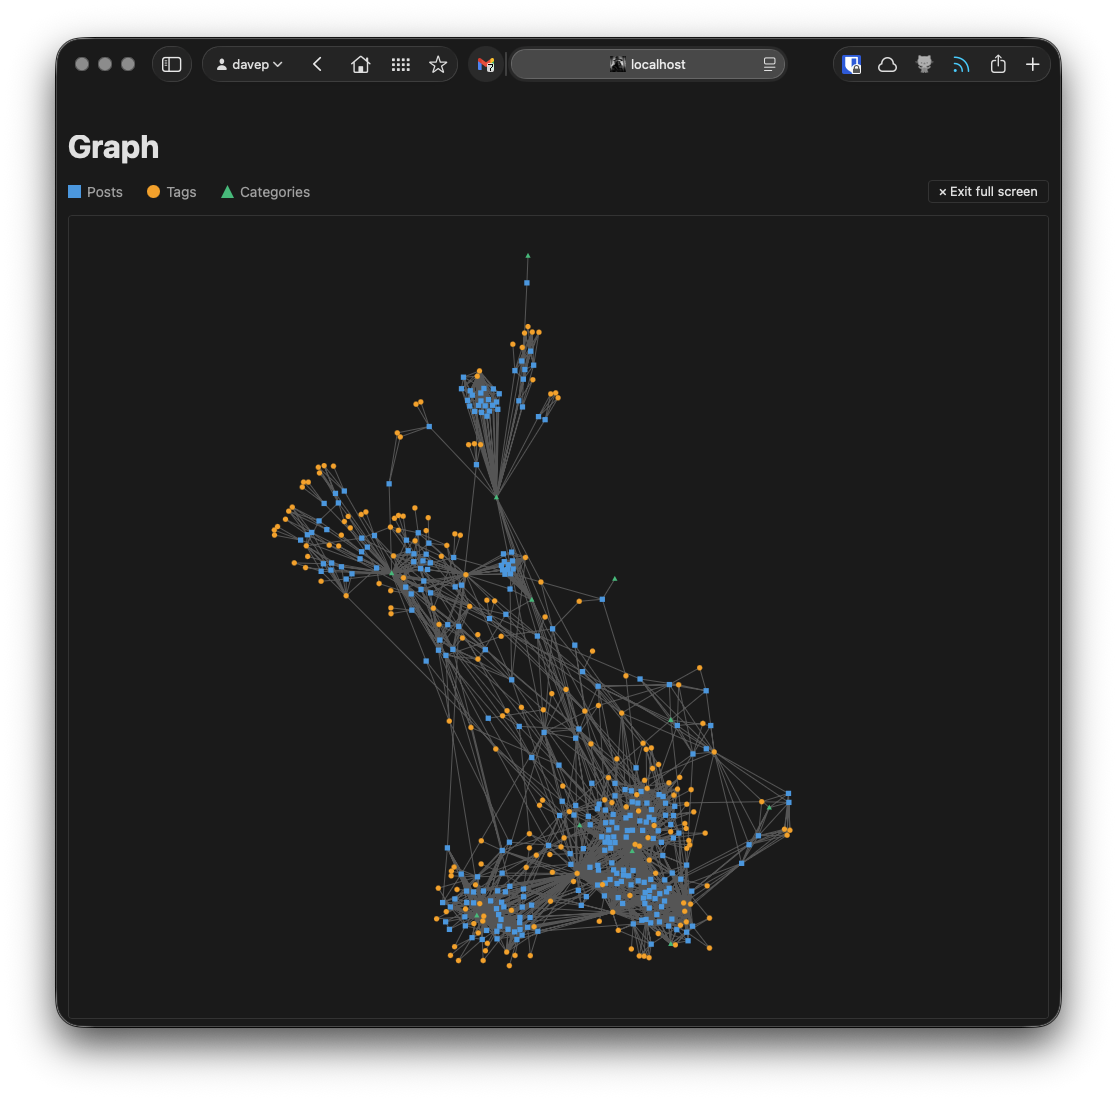
Given the nature of the graph and that the viewer is naturally going to want to explore, it can be toggled into a "full screen" (well, "mostly most of the page") mode too:

In full screen mode

The graph itself (built using force-graph) can be explored in the ways you'd reasonably expect, allowing zooming, panning around, dragging nodes around to get a better view of things, and so on.

Zoomed in on the graph

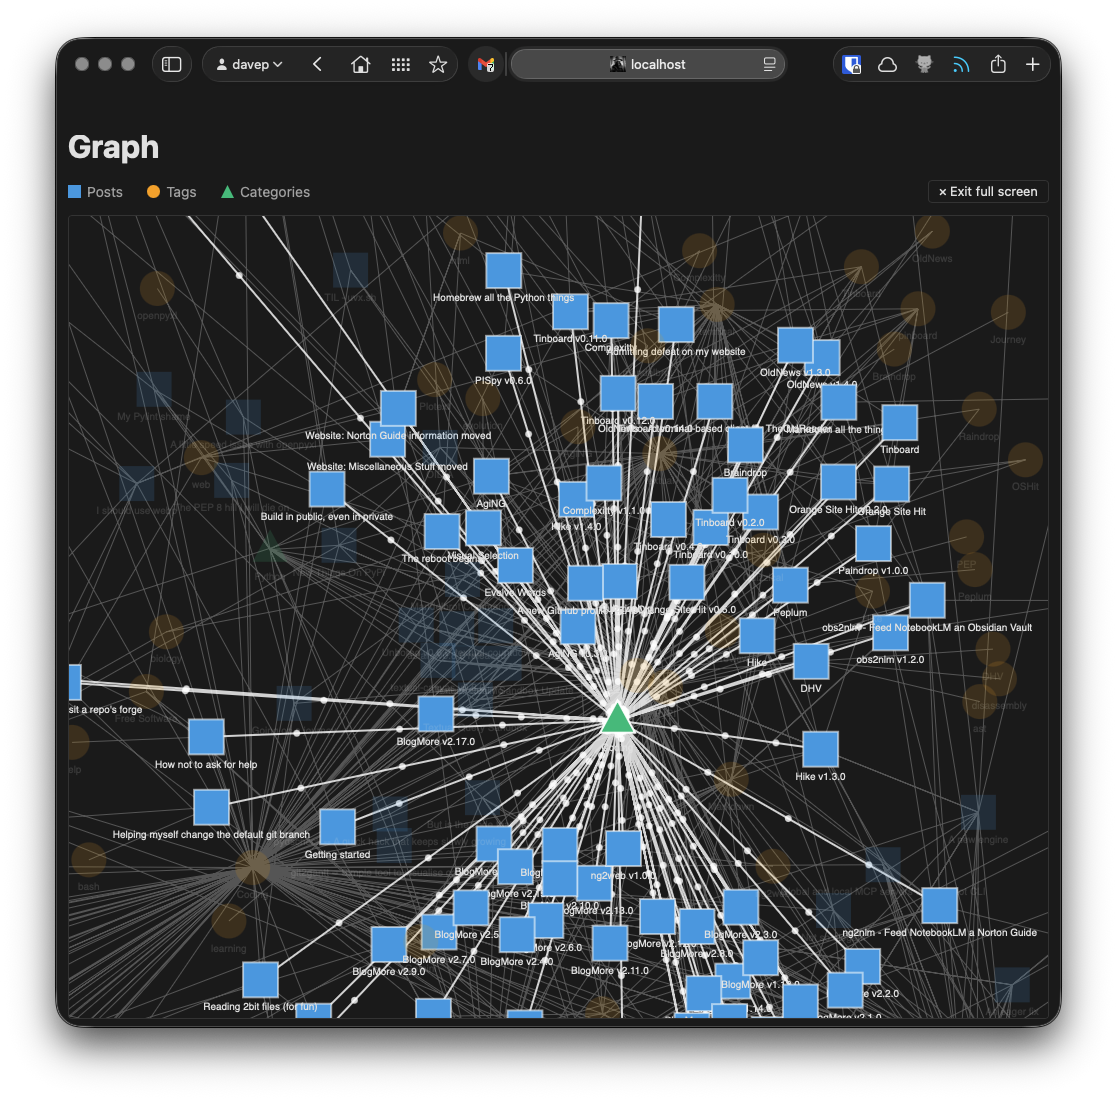
If you click on any of the nodes the graph will show you everything that's linked to it:

Highlighted links

and if you click the node again it will take you to the post, tag archive or category archive, depending on what it is you are clicking on.

So far I'm finding this is working really well as yet another method of discovering posts and themes, etc; it's already helped me find some "under-used" tags that deserved to be added to posts to better connect things. I suspect the feature will need refining over time, especially from a cosmetic point of view, but the result feels very usable as it stands.

BlogMore v2.16.0

1 min read; 10 GFI

BlogMore has had a new release, bumping the version to v2.16.0. There are two main changes in this update, both coming from a single idea: internal back-links.

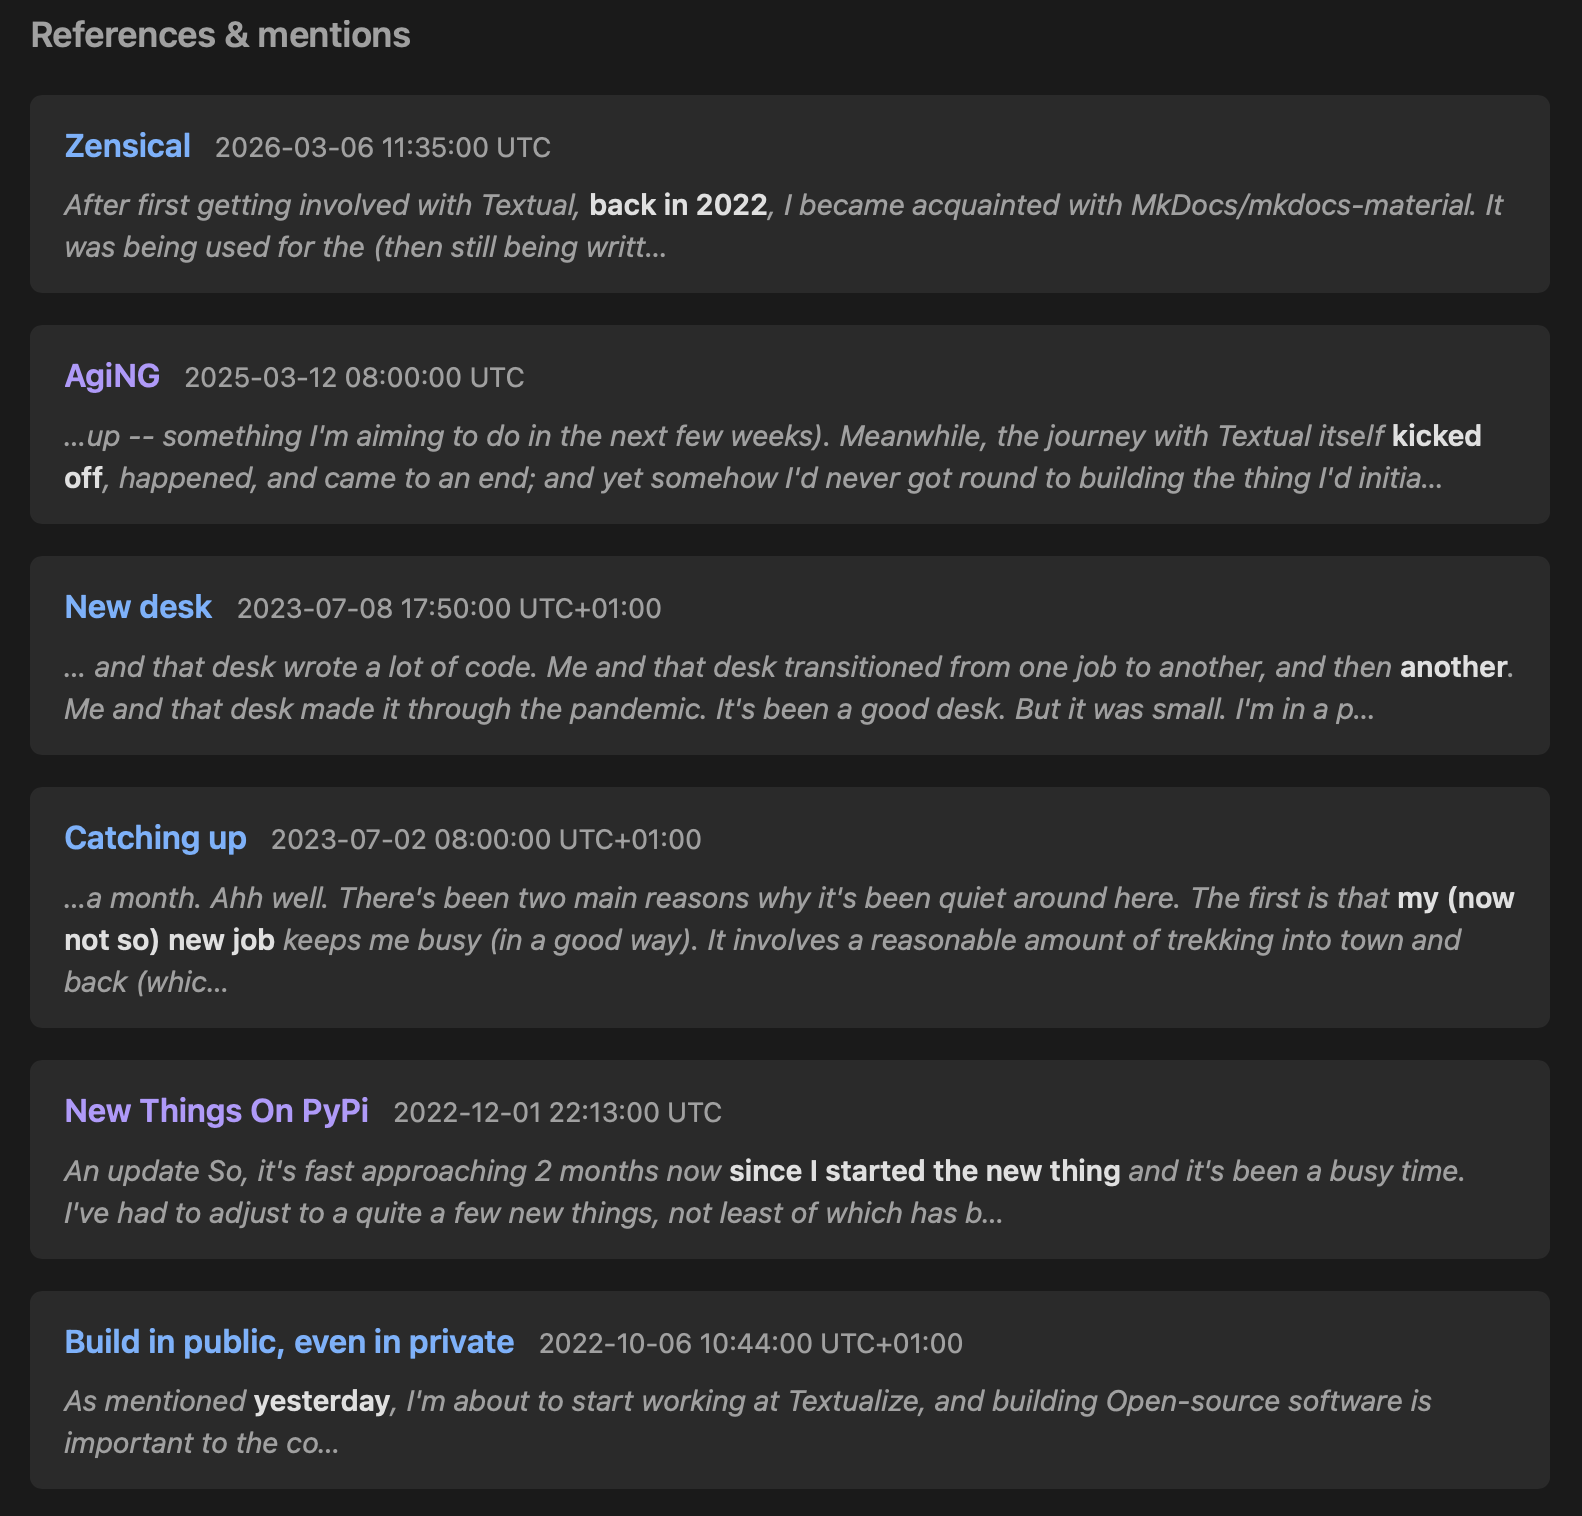
Where it makes sense, I always try and link posts in this blog to other related posts, but I've never really had a sense of how interconnected things are. So, the first new thing I added was a with_backlinks configuration option. This is off by default, but when turned on, will add a list of any referring posts to the bottom of a post.

A list of references to a post

Like some of the work I did in the stats page, this feels like another interesting method of discovering posts and related subjects within a blog.

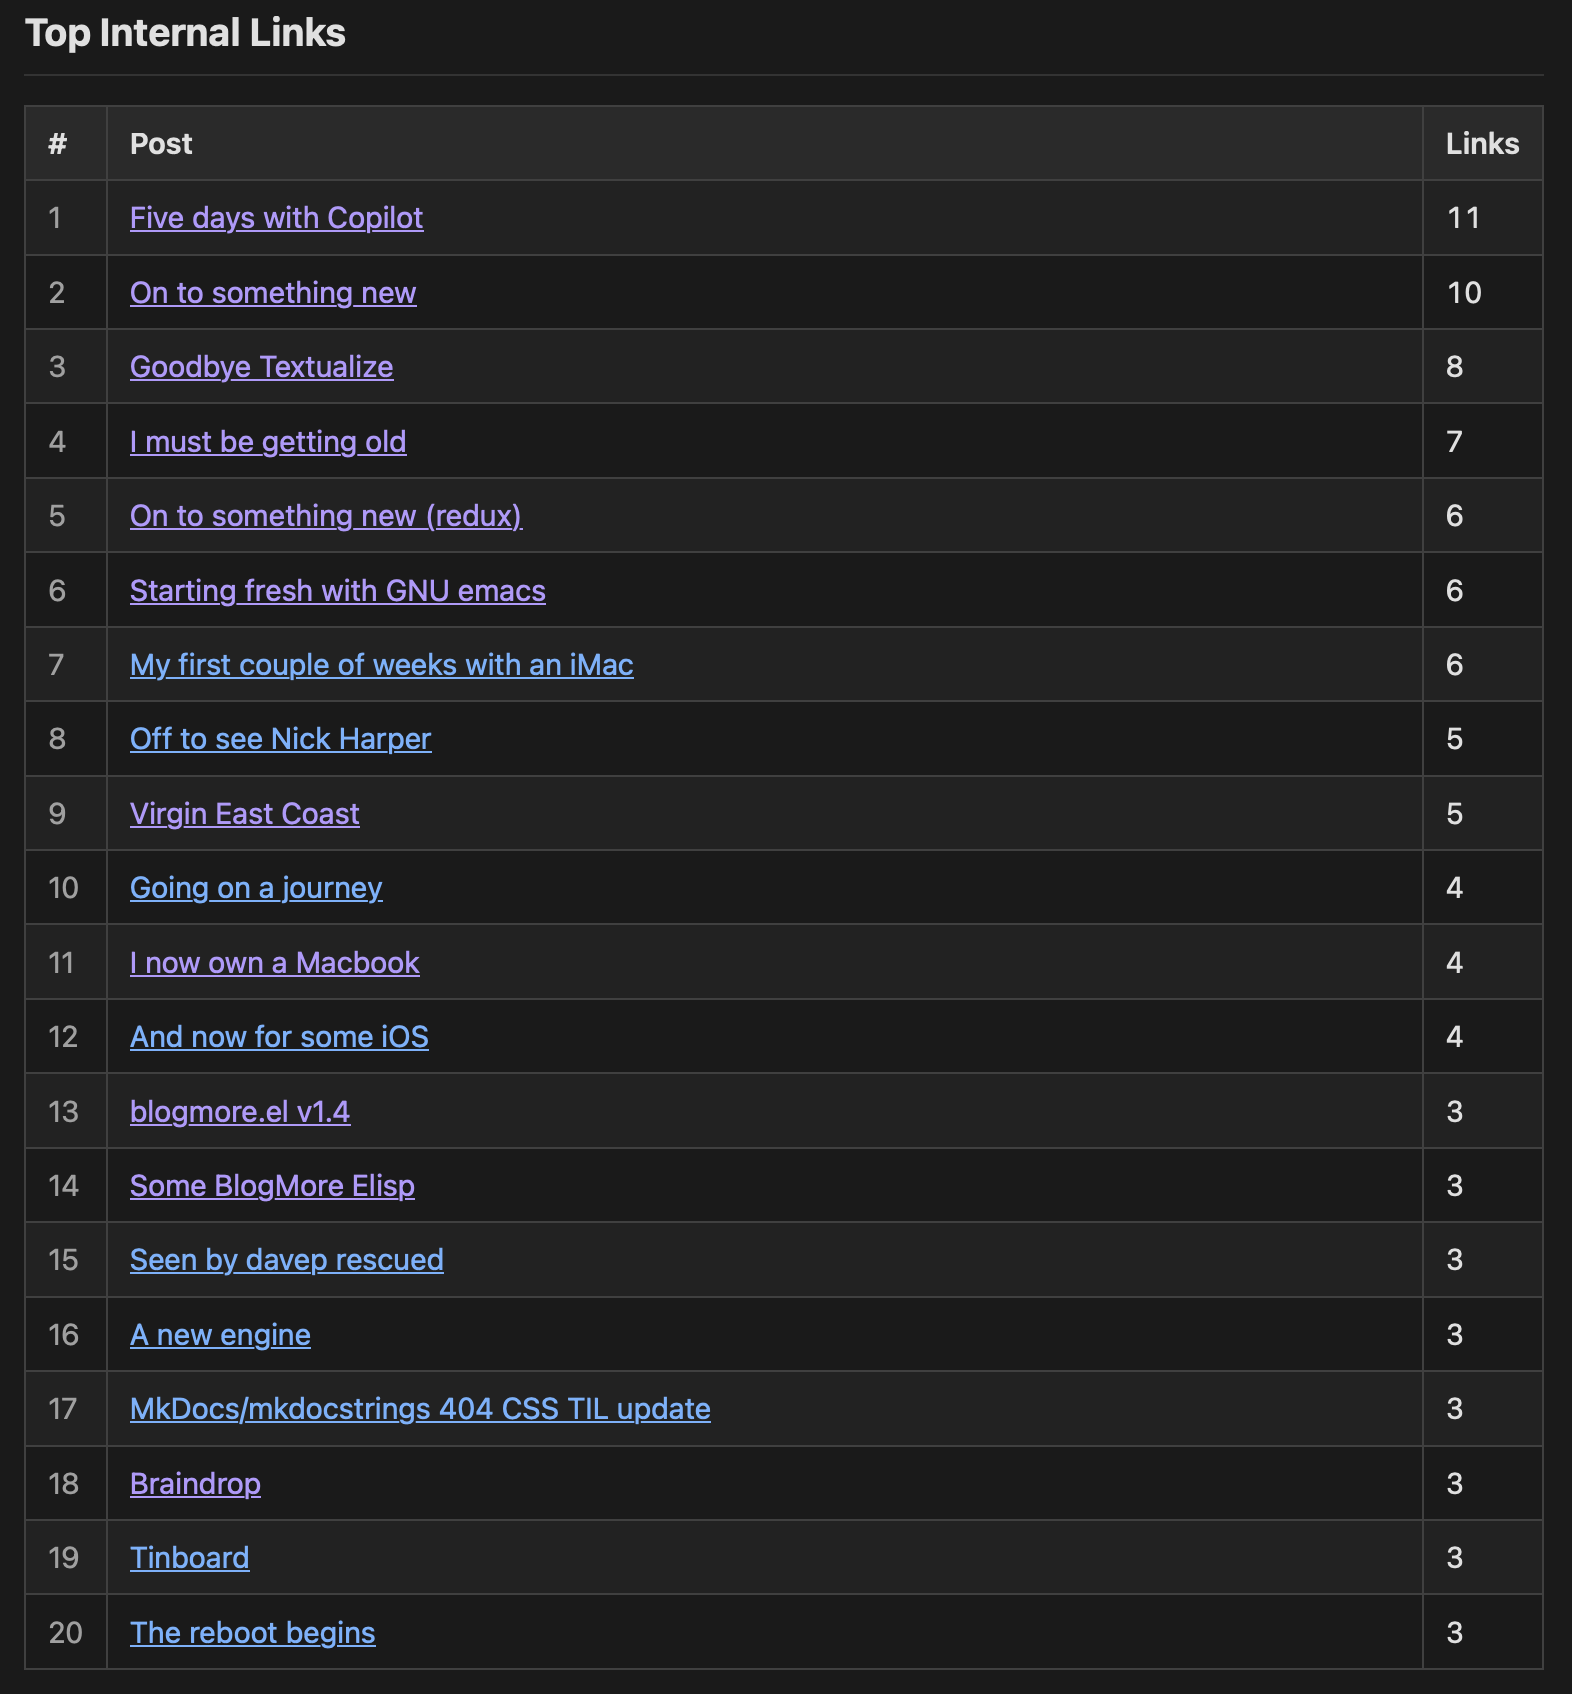
Once this work was done, it seemed to make sense to use the link-gathering code to then get a sense of which posts are most often linked to within a blog, and so a table of most-linked posts has been added to the stats page.

Internal link stats

This particular table will only appear in the stats if with_backlinks is set to true.

At some point in the future it might be interesting to take this even further and produce a map of interconnected posts; for now though I think this is enough.

BlogMore v2.15.0

1 min read; 5 GFI

I've just made a small update to BlogMore. This fixes a minor cosmetic issue that's been bugging me for a while, but one that I kept forgetting to address. I noticed it again on a recent post. The issue is that if there are enough tags on a post that the collection of tags runs to a second line, there was no space between those lines.

Before

Now, as of v2.15.0, there's a little bit of breathing room between those lines.

After

Much better.

BlogMore v2.14.0

1 min read; 8 GFI

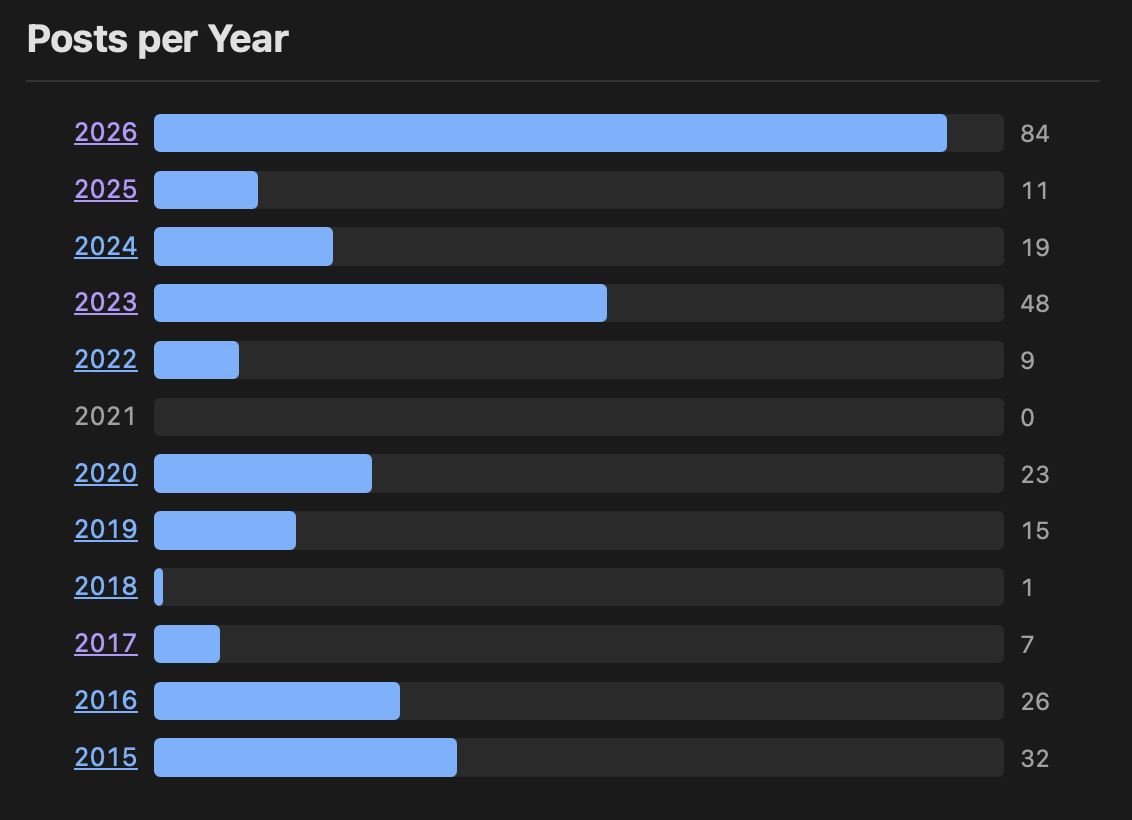
Quick little update for BlogMore, with a bump up to v2.14.0. This release comes from another feature request from Andy1, where he asked if it would be possible to have a year-based bar chart in the stats page.

Funnily enough I'd been thinking about the same thing just yesterday. I'd been wondering if it was worth adding, or if it would be overkill given the numbers can be seen in the archive. Having been asked by someone else... that was all the prompting I needed to kick that off.

Posts per year for my blog

Now I'm glad I did this. I like the result, it's a different way to visualise the values, and it's yet another way for people to discover past posts on the blog.

For sure BlogMore is now feature complete.


  1. Who recently wrote an interesting article about his experience of migrating his blog from Hugo to BlogMore ↩

BlogMore v2.13.0

1 min read; 12 GFI

Following on from yesterday's release of BlogMore, I've been looking at some more information in the Google Search Console, which helped me uncover a couple more bugs in relation to URL generation.

This time I noticed a couple of issues, both related to the clean_urls setting. The first was that, in the recently added calendar page, all of the URLs for the links into the date-based archive weren't taking clean_urls into account. That's now fixed.

The second problem was the canonical <link> tag in the headers of the various archive pages (categories, tags, date-based): none of the URLs used in the tag were being cleaned up if clean_urls was true. That's now also fixed.

The main "problem" those two issues were causing was Google was seeing the sitemap for my blog declare one URL, but discovering different versions of the URL elsewhere; the main offending part here being the canonical URL declaration that disagreed with the sitemap.

To the best of my understanding the above fixes should clean a lot of that up.

Also in this new release is a small new feature. After cleaning up the sitemap generation in v2.12.0 I got to thinking that, perhaps, there would be occasions where a user would want to be able to add extra items to the sitemap. With this in mind I've added the sitemap_extras configuration property. With this you can declare extra URLs to drop into the sitemap, if one is being generated.

sitemap_extras:
  - /some/path/
  - /some/file.html

I don't think I have a use for this right now, I'm not sure I'll ever have a use for it, but it feels like a low-cost feature to add that could be useful to someone at some point.

obs2nlm v1.2.0

1 min read; 9 GFI

Three months back I released obs2nlm, a tool that takes an Obsidian vault and turns it into a single Markdown file so it can be used as a source for NotebookLM.

Since then I've been using it a lot and it's working out really well.

Meanwhile, one of my vaults has started to creep up towards the documented word limit for a single source in NotebookLM (500,000 words). Right now it's sitting at around 75% and is steadily creeping up.

So, with this in mind, I've made a change I've been planning from the start and have added a --split option. If used, if the generated file looks like it's going to hit the word limit, a second (or more) file will be created. The naming scheme is simple enough: if you ask obs2nlm to create an output file called dirt.md and it needs to run over, it'll then create dirt-2.md, dirt-3.md, and so on. The idea then is that, rather than upload that single Markdown file as a source, you upload all of the generated Markdown files.

Given you get up to 50 sources per notebook, this should see me right for any reasonable vault. As for if it will affect the quality of the results I get when I query the notebook... that's hard to say until I find myself in that situation. If Google are to be believed it shouldn't be an issue, and the alternative is to fall foul of the limit so this seems like the only sensible solution.

I've also added a --dry-run command line switch too; this should be handy for checking how big a vault is when compared to the word limit, without actually generating any files.

BlogMore v2.12.0

1 min read; 9 GFI

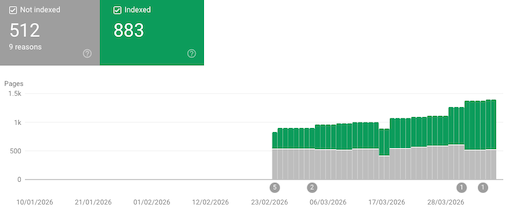
Since kicking off building BlogMore and swapping this blog over to using it I've been playing with the Google Search Console. It's something I've not used in decades, but felt it was time to dip back in again and understand how it works these days.

There are two motivations for this: the first is that, when it comes to my day job, I have cause to interact with people who do use the search console a lot, and so it's worth understanding what they work with and why it matters to them. The second reason is it's a reasonable measure of how good a site BlogMore generates.

Page index inclusion progress

So far the results have been pretty good, and the console has helped me find oddities and things that need tidying up.

So this release of BlogMore includes a couple of changes that stem from looking at the latest updates in the console.

The first is that I've cleaned up how the sitemap.xml gets generated. I noticed that if I had any HTML inside my extras directory it was turning up in the sitemap; something I didn't intend and didn't want. So that's now fixed: only pages generated by BlogMore will appear in sitemap.xml1.

The second is that the stats page, despite being in the sitemap, had a noindex header for some reason. That's now been fixed. The only generated page I've intentionally set up so that it isn't indexed is the search page.

Finally, there's one change unrelated to the above: I realised that if you have with_read_time set to false, the reading time stats still appeared on the stats page; that seems unnecessary and unwanted on a site that doesn't show reading times. So, as of v2.12.0, that section of the stats won't show if reading times are turned off.


  1. Now I think about it, I suppose there might be occasion where someone wants extra HTML to appear in the sitemap. I might consider the idea of allowing extra entries to be declared via the configuration file. ↩